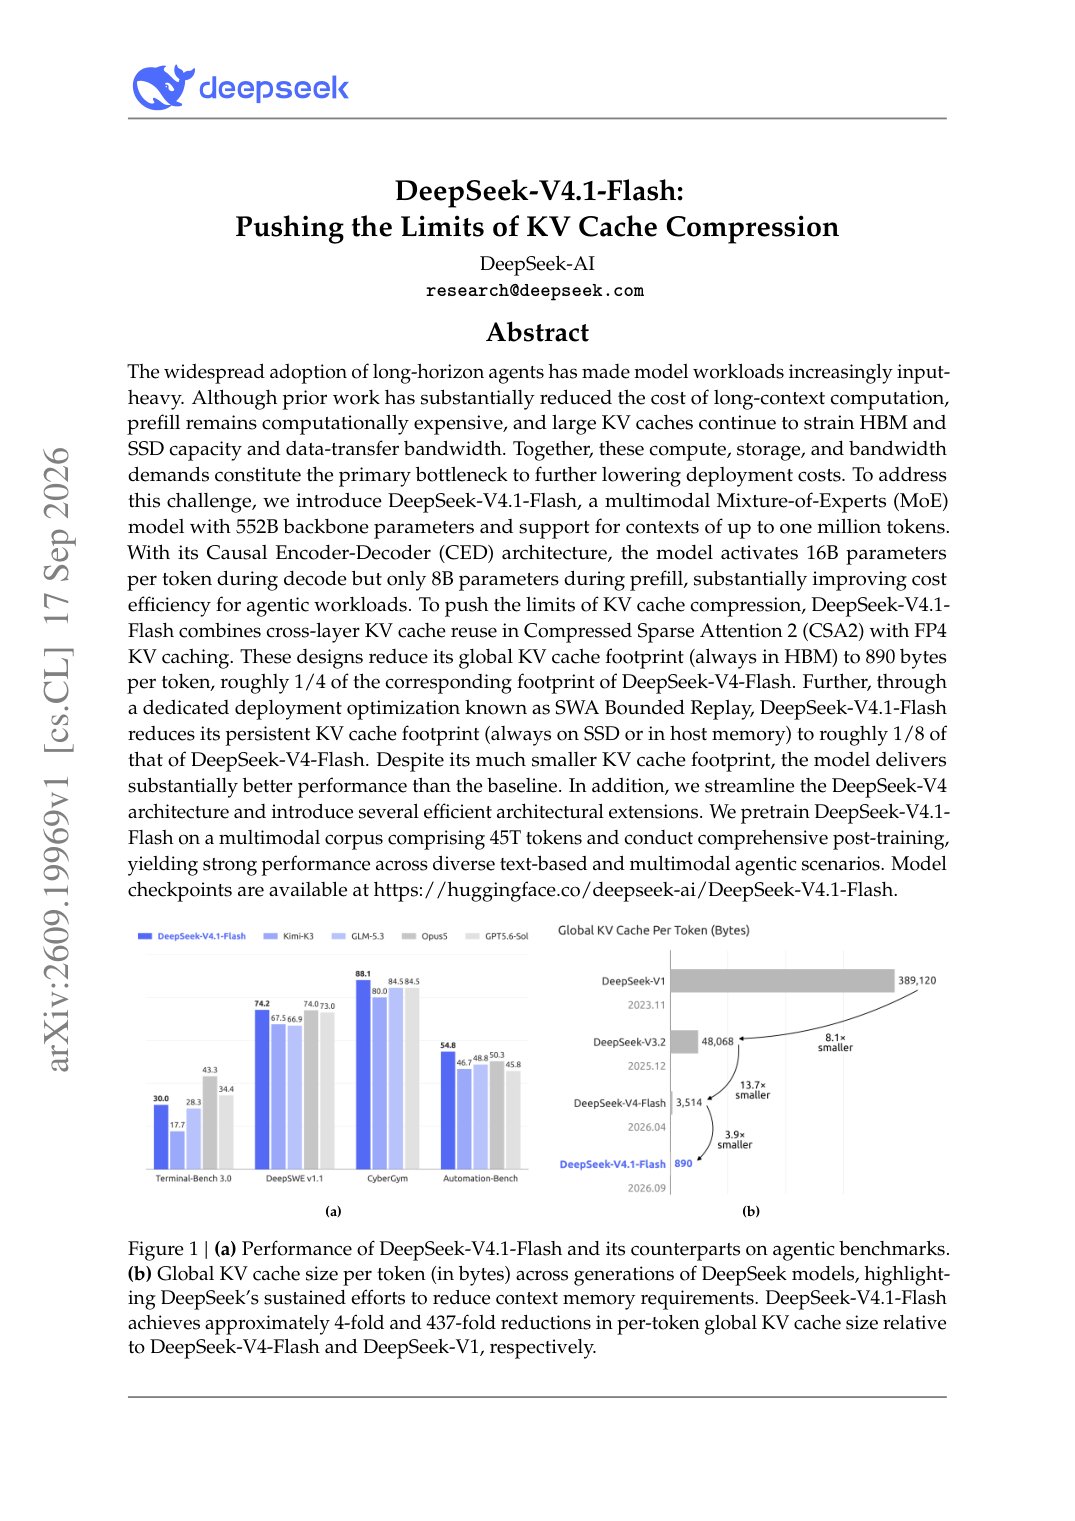
DeepSeek Cuts KV Cache Footprint Fourfold
A causal encoder-decoder MoE pairs cross-layer sparse-attention reuse with FP4 caching to reduce global context memory to 890 bytes per token.
Sep 19, 20264 min2609.19969
4 articles on SOTA Papers
A causal encoder-decoder MoE pairs cross-layer sparse-attention reuse with FP4 caching to reduce global context memory to 890 bytes per token.
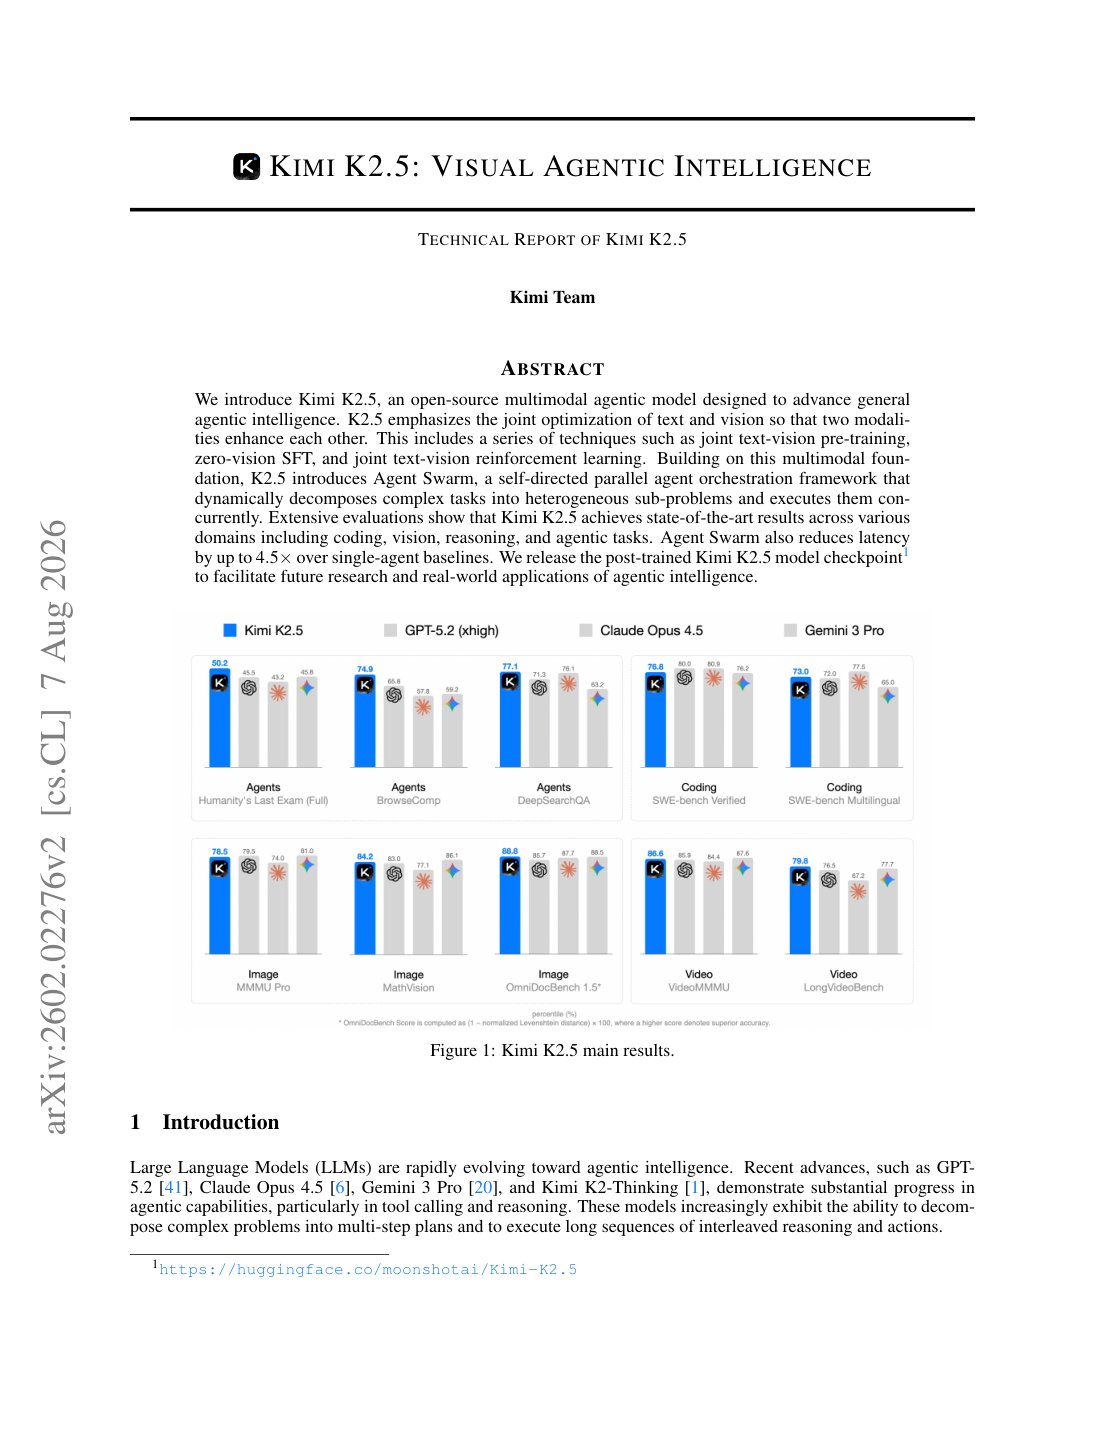
Kimi K2.5 couples joint text-vision training with dynamically scheduled parallel subagents, improving agentic search scores while reducing time to target quality.
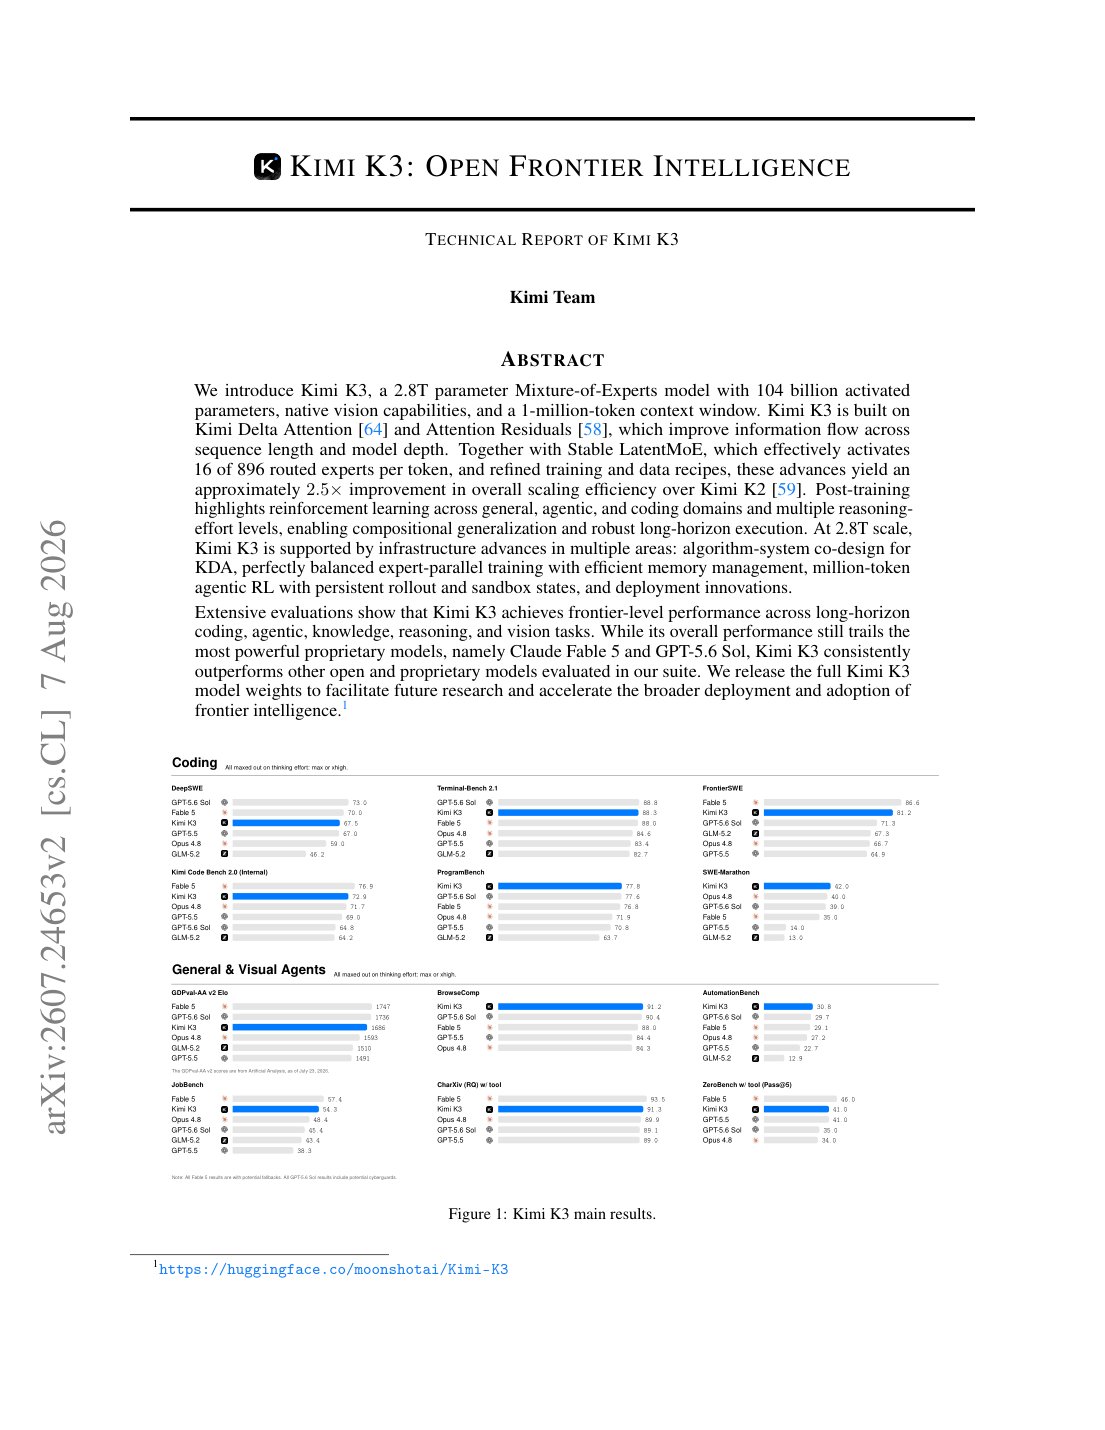
A 2.8T-parameter MoE combines Delta Attention, 16-of-896 expert routing, and agentic reinforcement learning to approach leading proprietary systems at lower task cost.
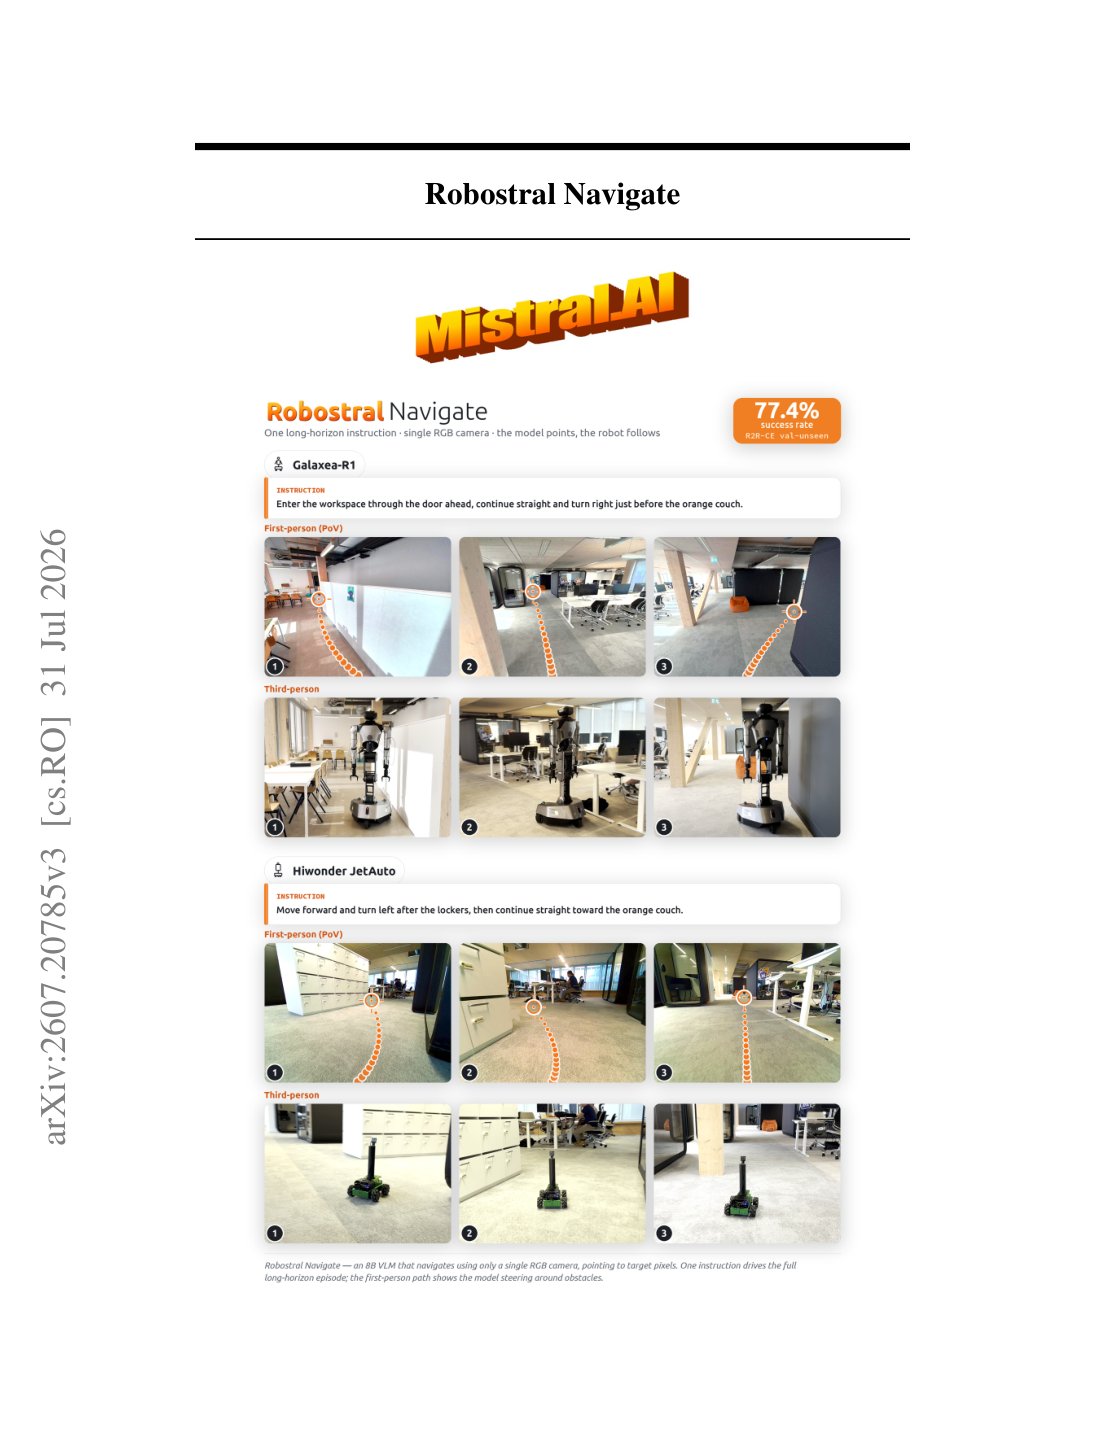
An 8B vision-language model predicts image-space waypoints from a single RGB stream, reaching 77.4% unseen-environment success while cutting supervised training tokens 22×.