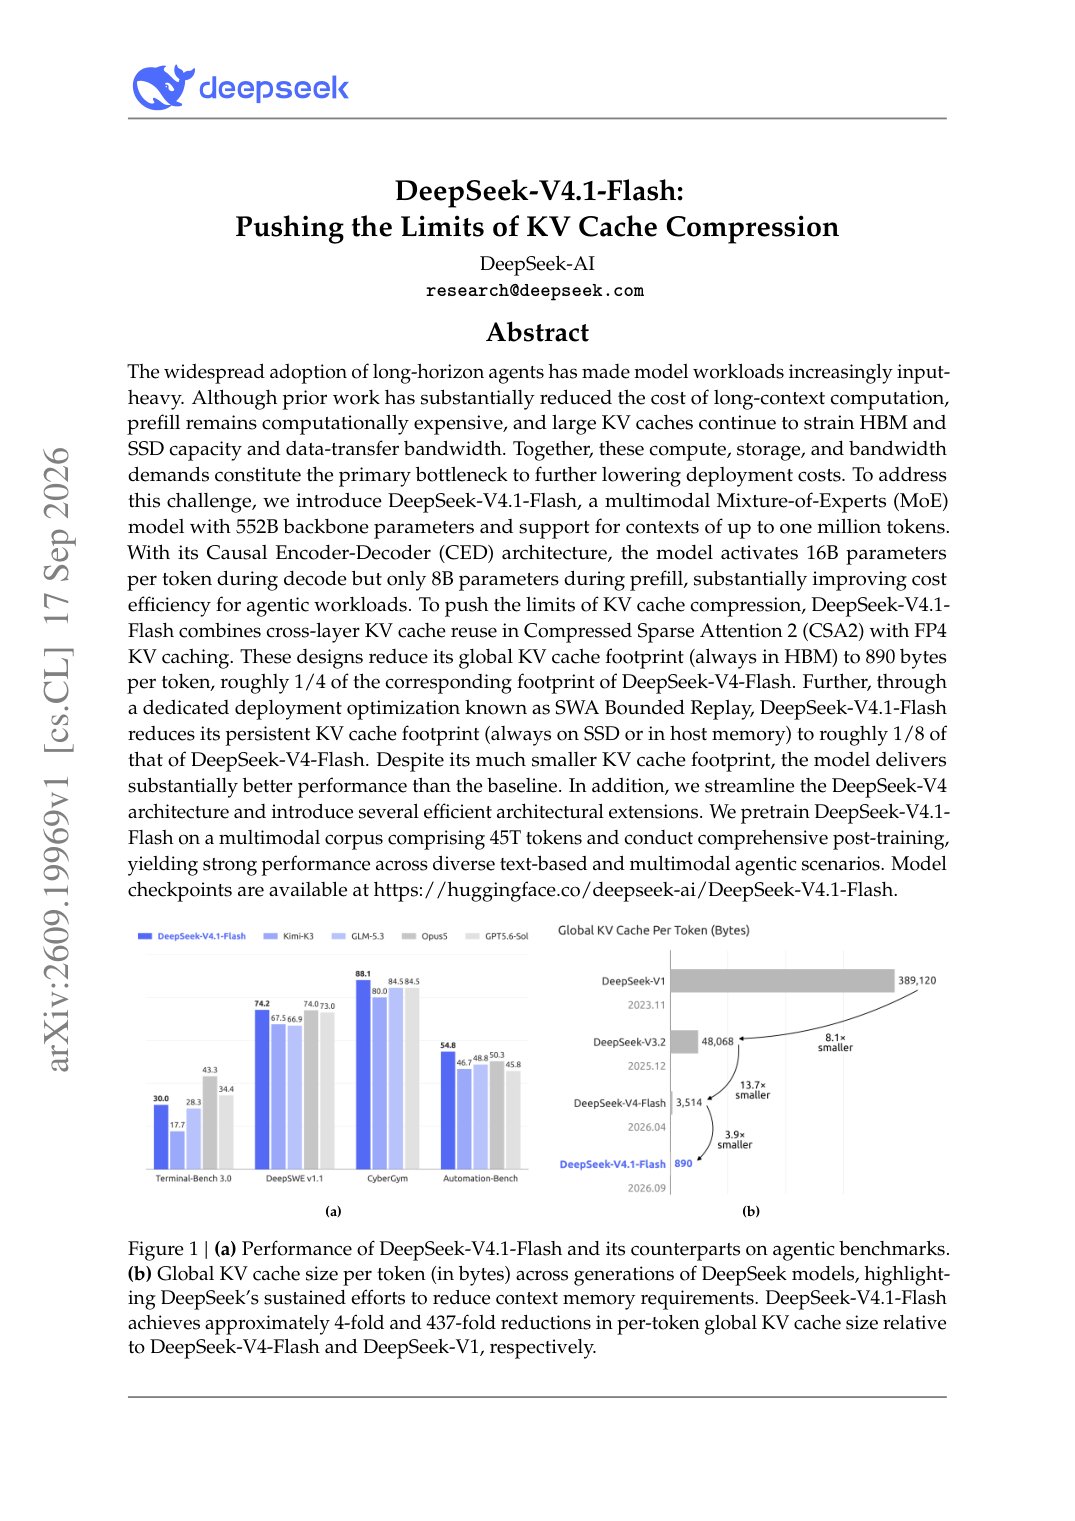
DeepSeek Cuts KV Cache Footprint Fourfold
A causal encoder-decoder MoE pairs cross-layer sparse-attention reuse with FP4 caching to reduce global context memory to 890 bytes per token.
Sep 19, 20264 min2609.19969
2 articles on SOTA Papers
A causal encoder-decoder MoE pairs cross-layer sparse-attention reuse with FP4 caching to reduce global context memory to 890 bytes per token.
A compact knowledge-base backbone queries full user histories at each layer, improving offline ranking metrics while cutting per-example FLOPs by 8×–25×.
