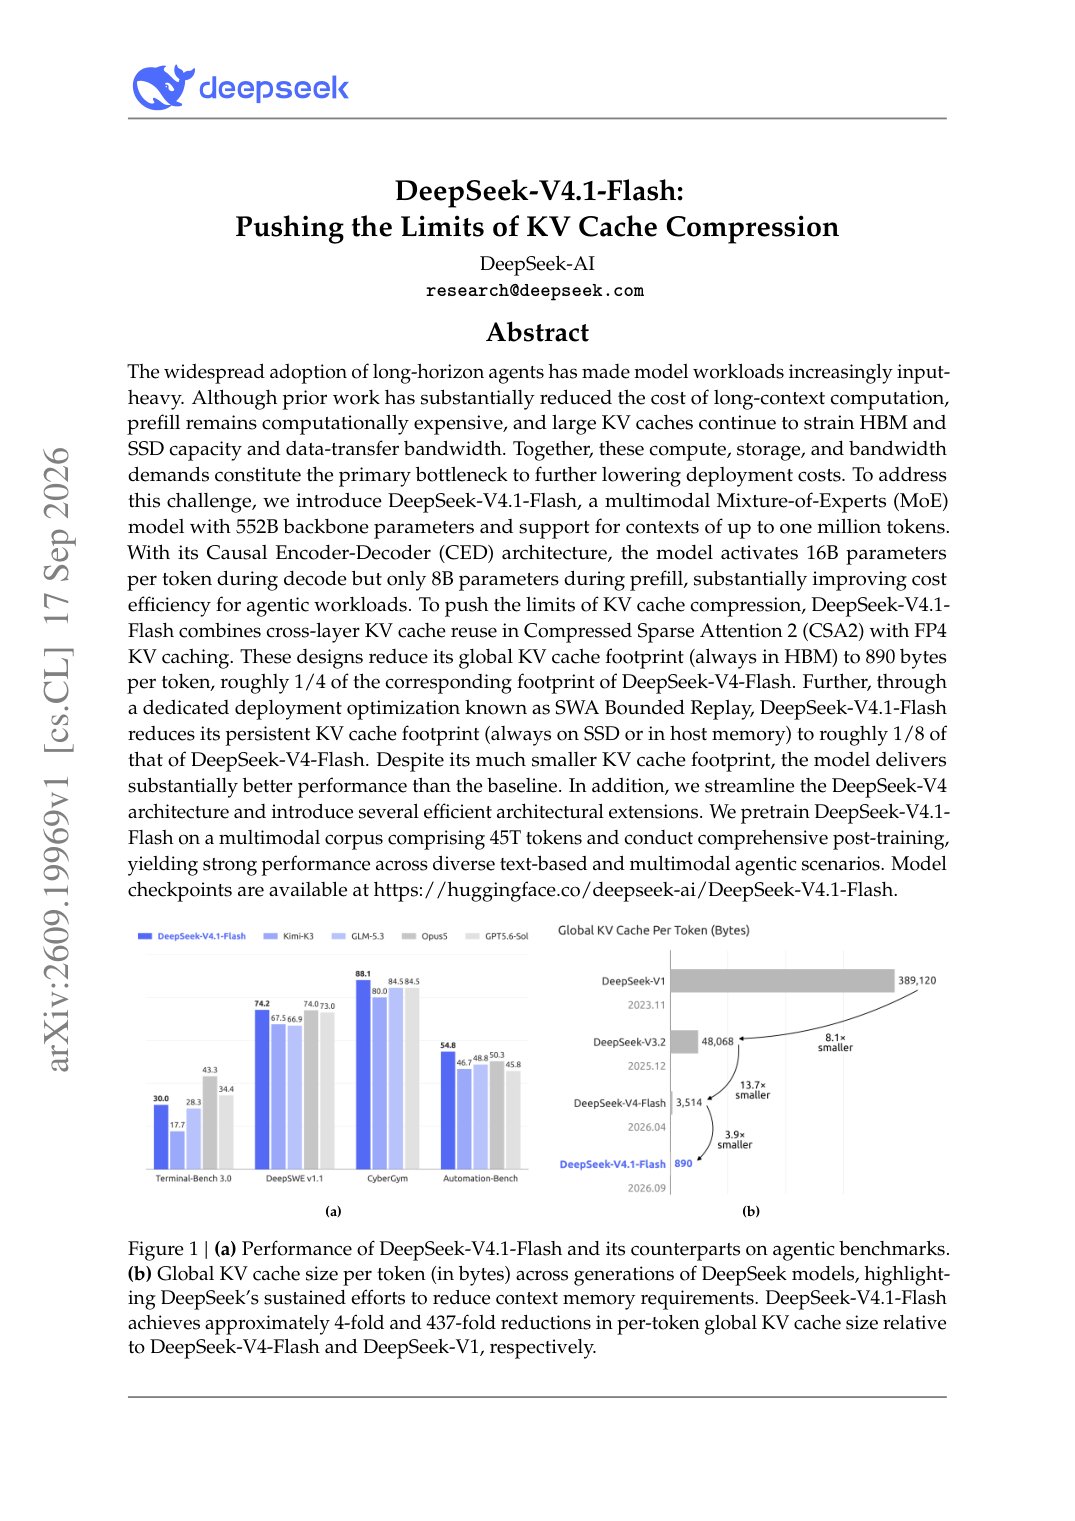
DeepSeek Cuts KV Cache Footprint Fourfold
A causal encoder-decoder MoE pairs cross-layer sparse-attention reuse with FP4 caching to reduce global context memory to 890 bytes per token.
Sep 19, 20264 min2609.19969
2 articles on SOTA Papers
A causal encoder-decoder MoE pairs cross-layer sparse-attention reuse with FP4 caching to reduce global context memory to 890 bytes per token.
Long-horizon trajectories, domain teachers, and routed on-policy distillation produce 56.4 on SEAL-0 and 80.6 on IFBench.
