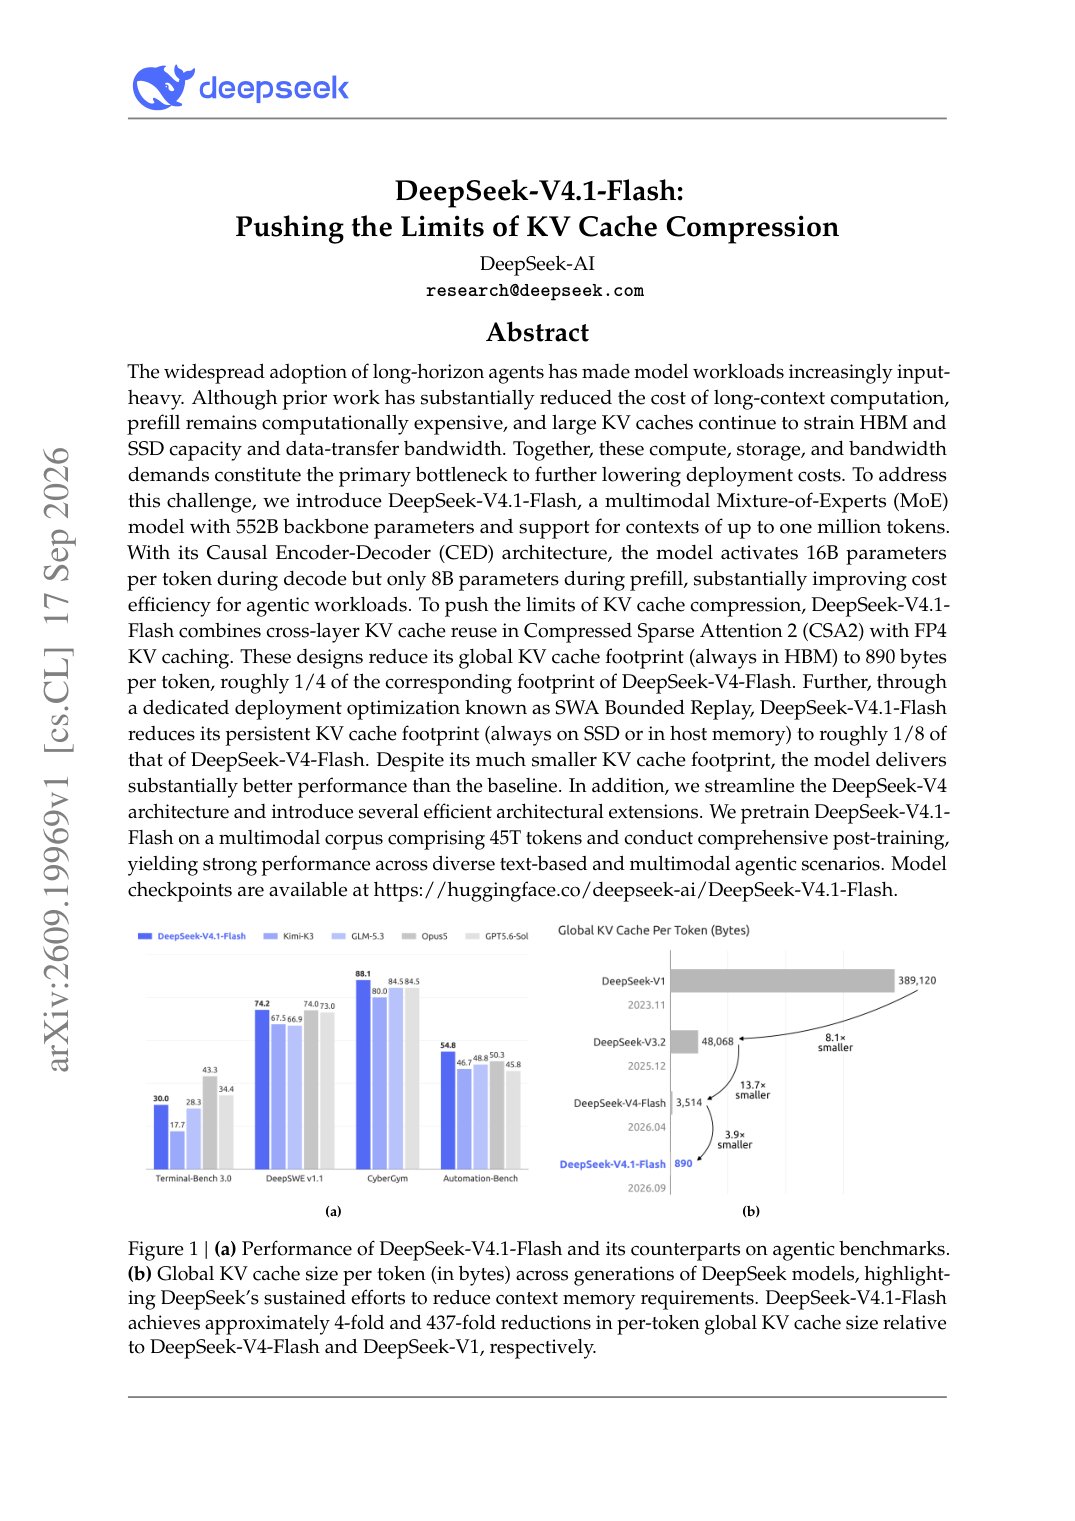
DeepSeek Cuts KV Cache Footprint Fourfold
A causal encoder-decoder MoE pairs cross-layer sparse-attention reuse with FP4 caching to reduce global context memory to 890 bytes per token.
Sep 19, 20264 min2609.19969
4 articles on SOTA Papers
A causal encoder-decoder MoE pairs cross-layer sparse-attention reuse with FP4 caching to reduce global context memory to 890 bytes per token.
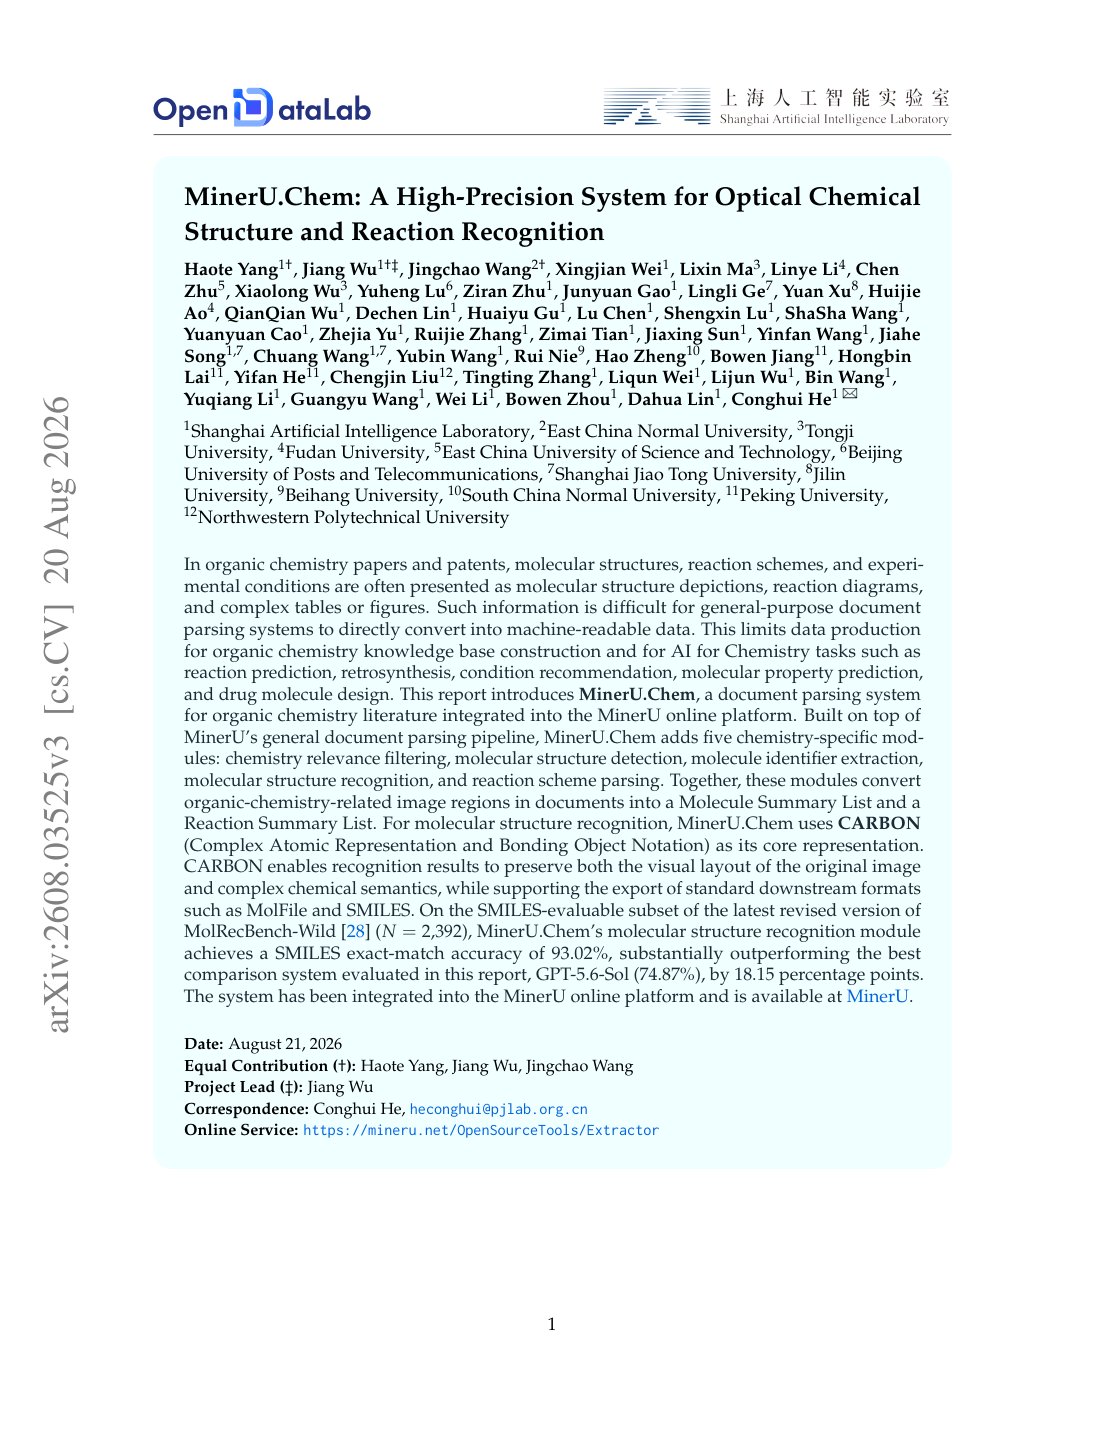
A chemistry-focused extension to MinerU converts document regions into molecule and reaction records, outperforming the evaluated GPT-5.6-Sol comparison on a SMILES benchmark subset.
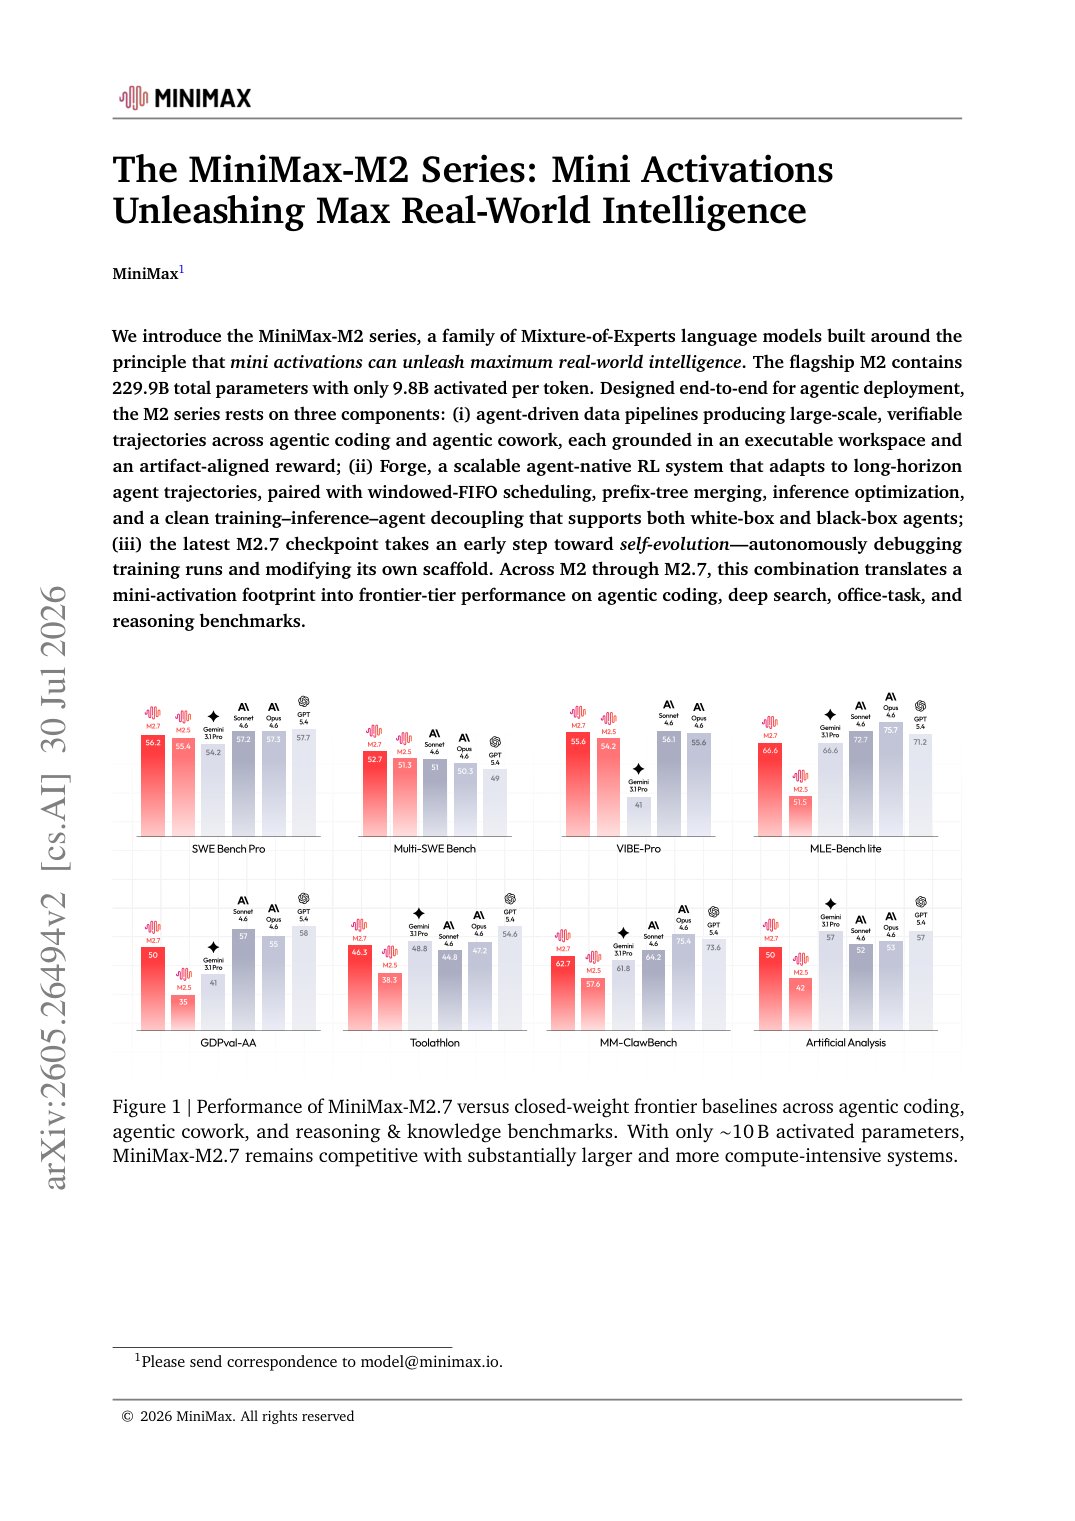
A sparse 229.9B-parameter MoE activates 9.8B parameters per token and pairs agent-native data with RL for coding, cowork, and reasoning tasks.
OrthoPilot combines hospital data retrieval with external medical knowledge, improving physician management success by 10.6% in 1,870 prospective complex cases.