DeepSeek Cuts KV Cache Footprint Fourfold
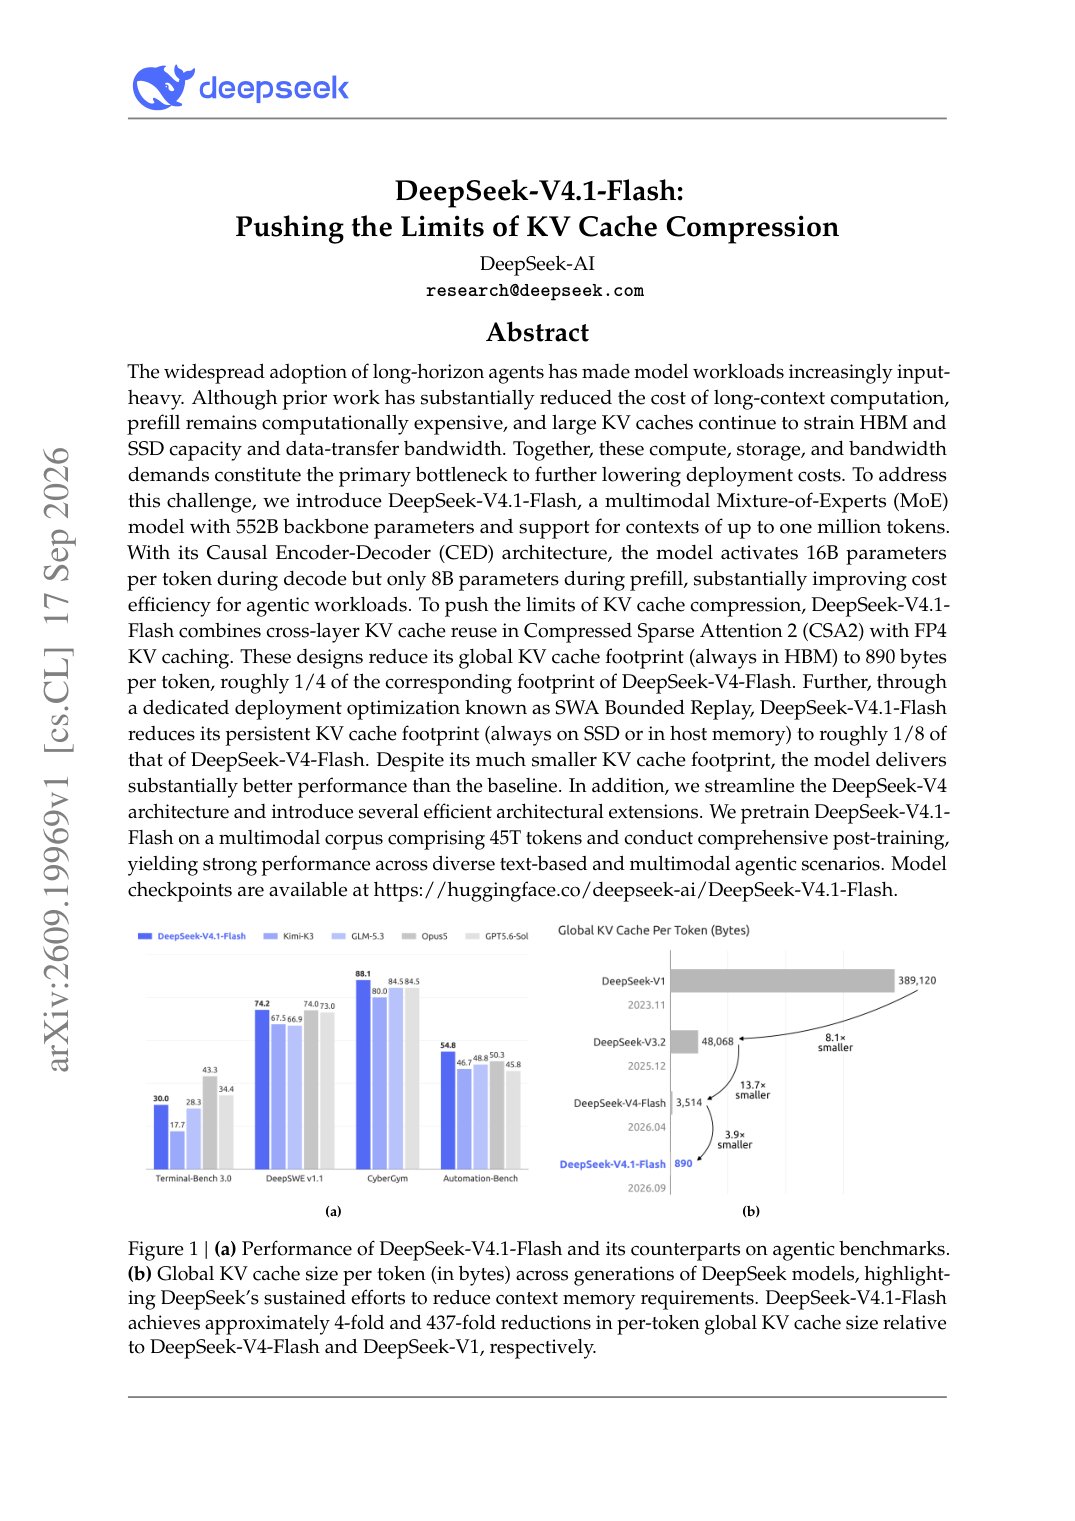
A causal encoder-decoder MoE pairs cross-layer sparse-attention reuse with FP4 caching to reduce global context memory to 890 bytes per token.
Sep 19, 20264 min2609.19969
4 articles on SOTA Papers
A causal encoder-decoder MoE pairs cross-layer sparse-attention reuse with FP4 caching to reduce global context memory to 890 bytes per token.
A chemistry-focused extension to MinerU converts document regions into molecule and reaction records, outperforming the evaluated GPT-5.6-Sol comparison on a SMILES benchmark subset.
FullDiT conditions a diffusion transformer on imperfect eight-stream codec plans, lyrics, and captions, improving ViSQOL by 0.77 under synthetic corruption.