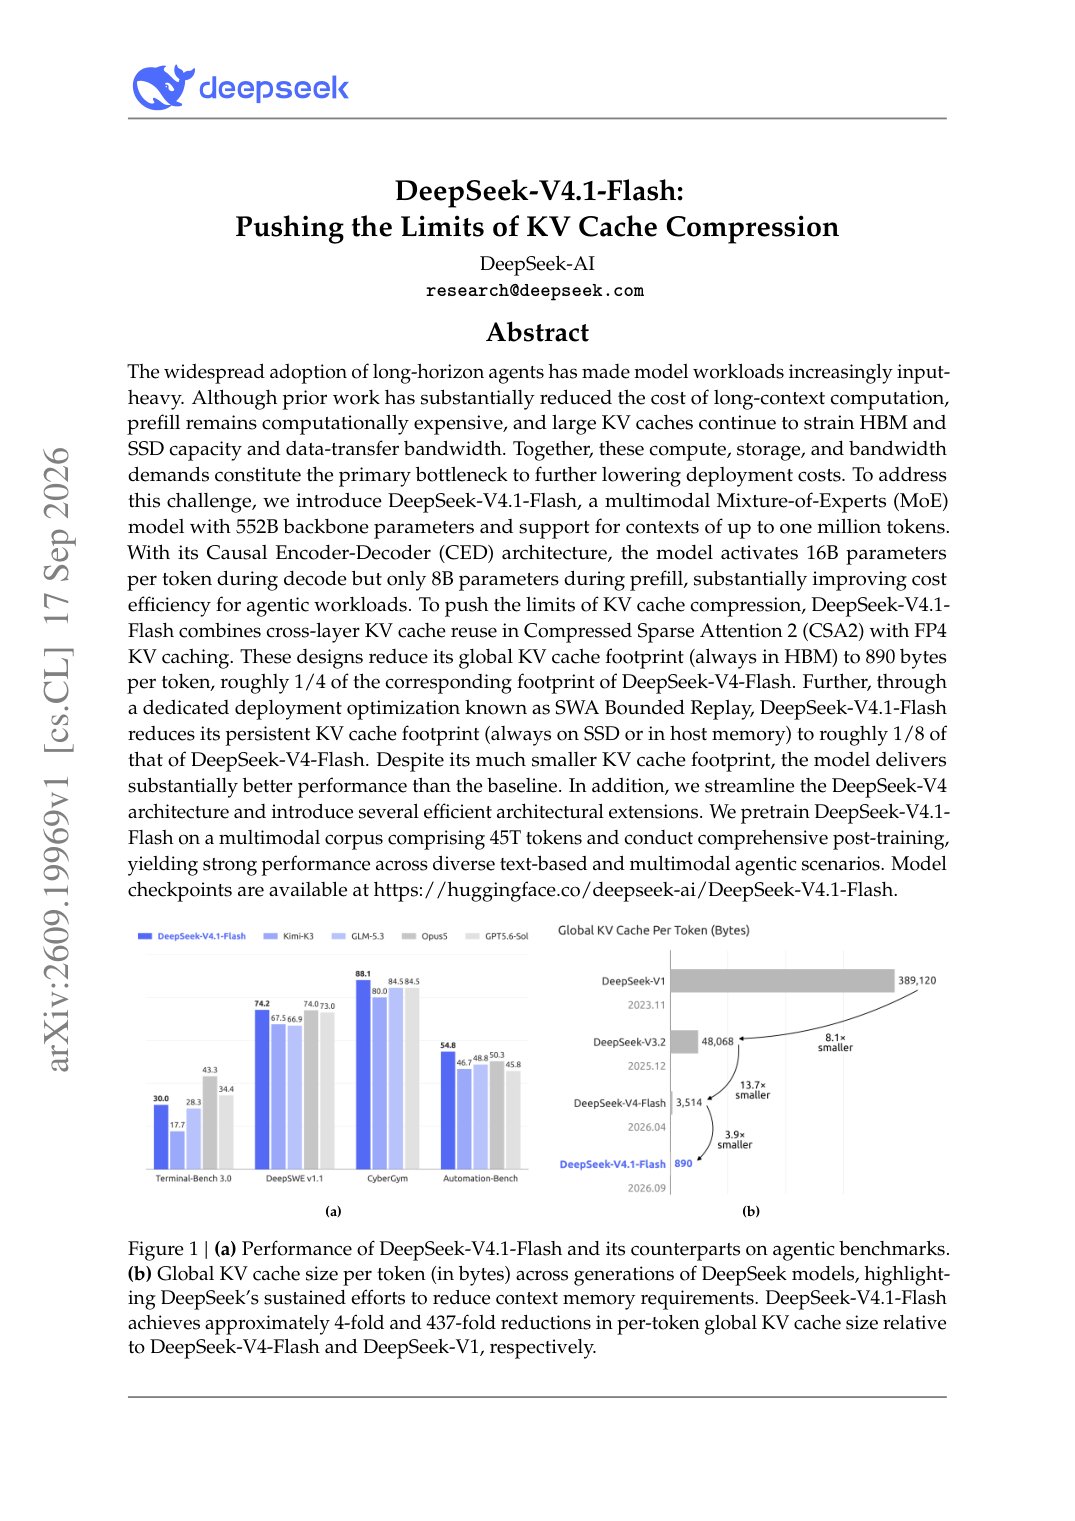
DeepSeek Cuts KV Cache Footprint Fourfold
A causal encoder-decoder MoE pairs cross-layer sparse-attention reuse with FP4 caching to reduce global context memory to 890 bytes per token.
Sep 19, 20264 min2609.19969
2 articles on SOTA Papers
A causal encoder-decoder MoE pairs cross-layer sparse-attention reuse with FP4 caching to reduce global context memory to 890 bytes per token.
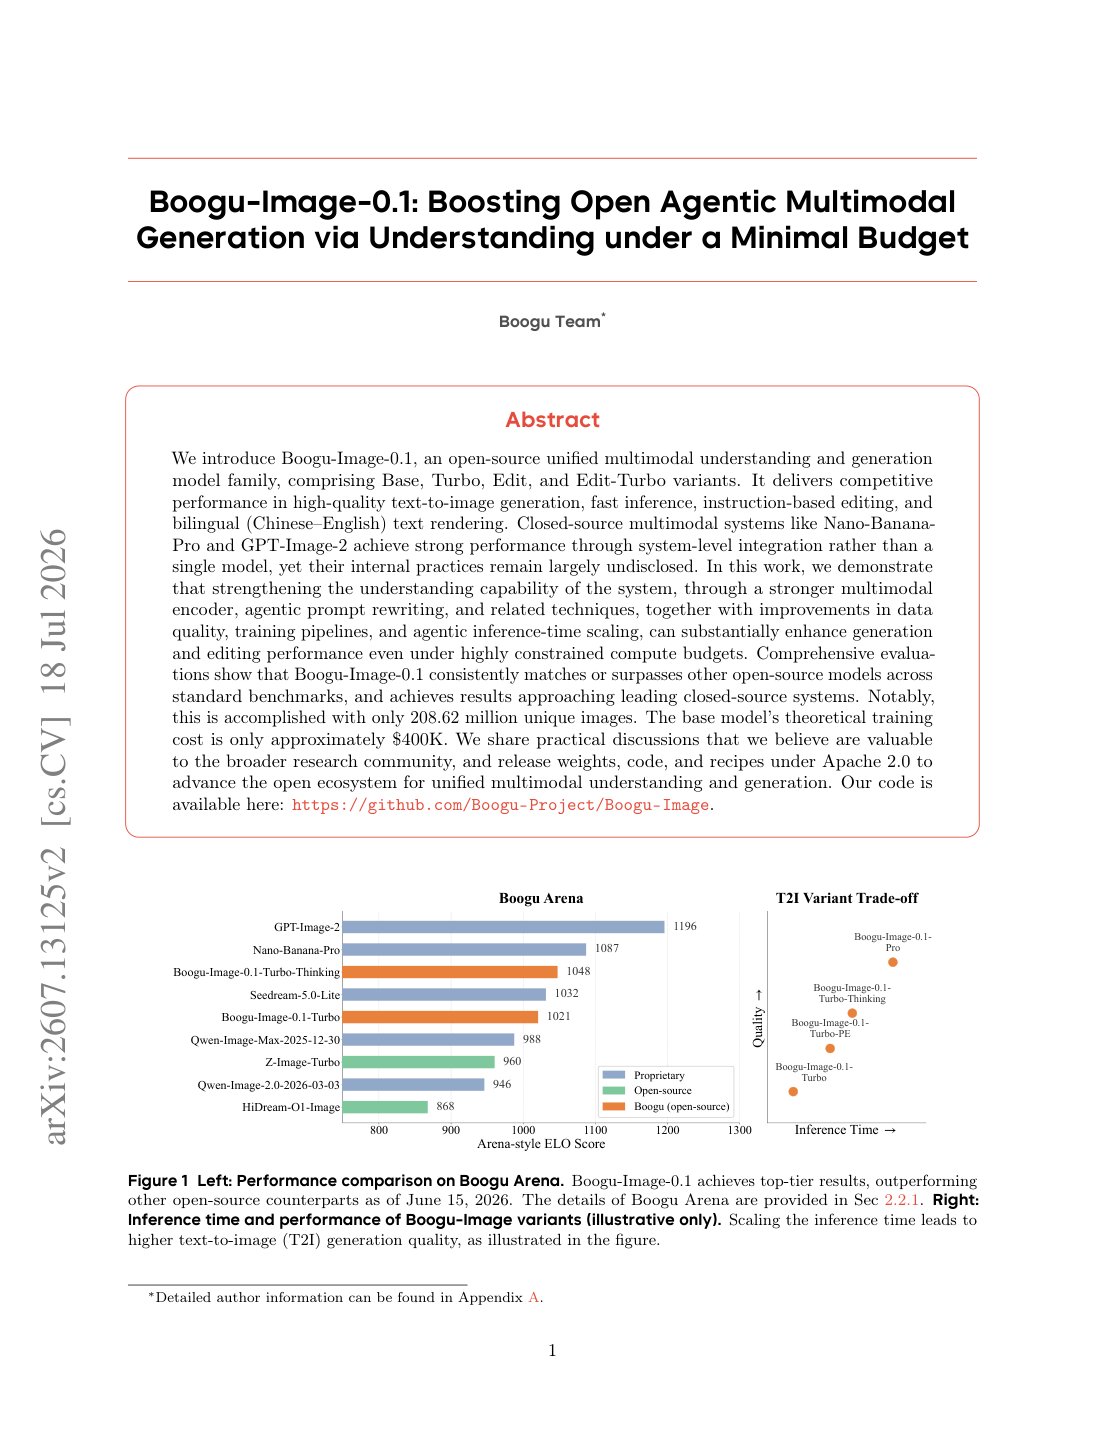
Boogu-Image-0.1 combines a stronger multimodal encoder, agentic prompt rewriting, and curated data to train competitive generation and editing models for about $400K.