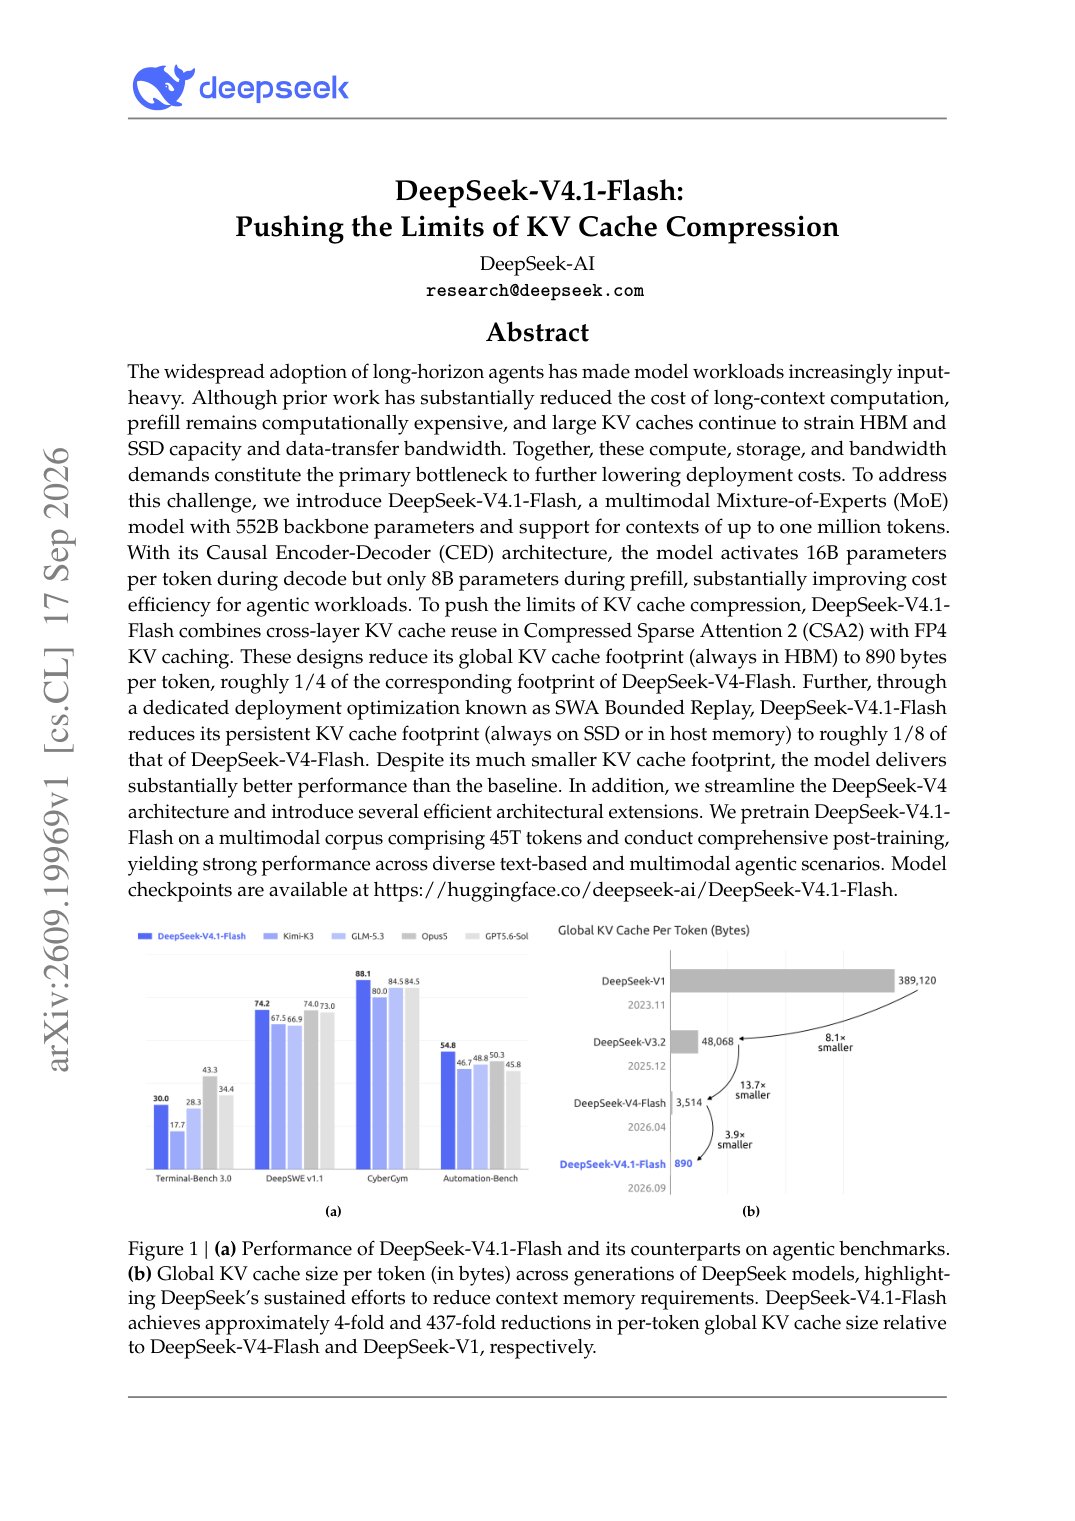
DeepSeek Cuts KV Cache Footprint Fourfold
A causal encoder-decoder MoE pairs cross-layer sparse-attention reuse with FP4 caching to reduce global context memory to 890 bytes per token.
Sep 19, 20264 min2609.19969
3 articles on SOTA Papers
A causal encoder-decoder MoE pairs cross-layer sparse-attention reuse with FP4 caching to reduce global context memory to 890 bytes per token.
Dense and MoE variants combine thinking traces, local-global attention, QAT, and MTP drafting, reaching 1451 Arena Elo with a 31B dense model.
A reconstruction-trained model over five wearable modalities improves prediction, imputation, and clinician-rated agent responses across 35 downstream health tasks.

