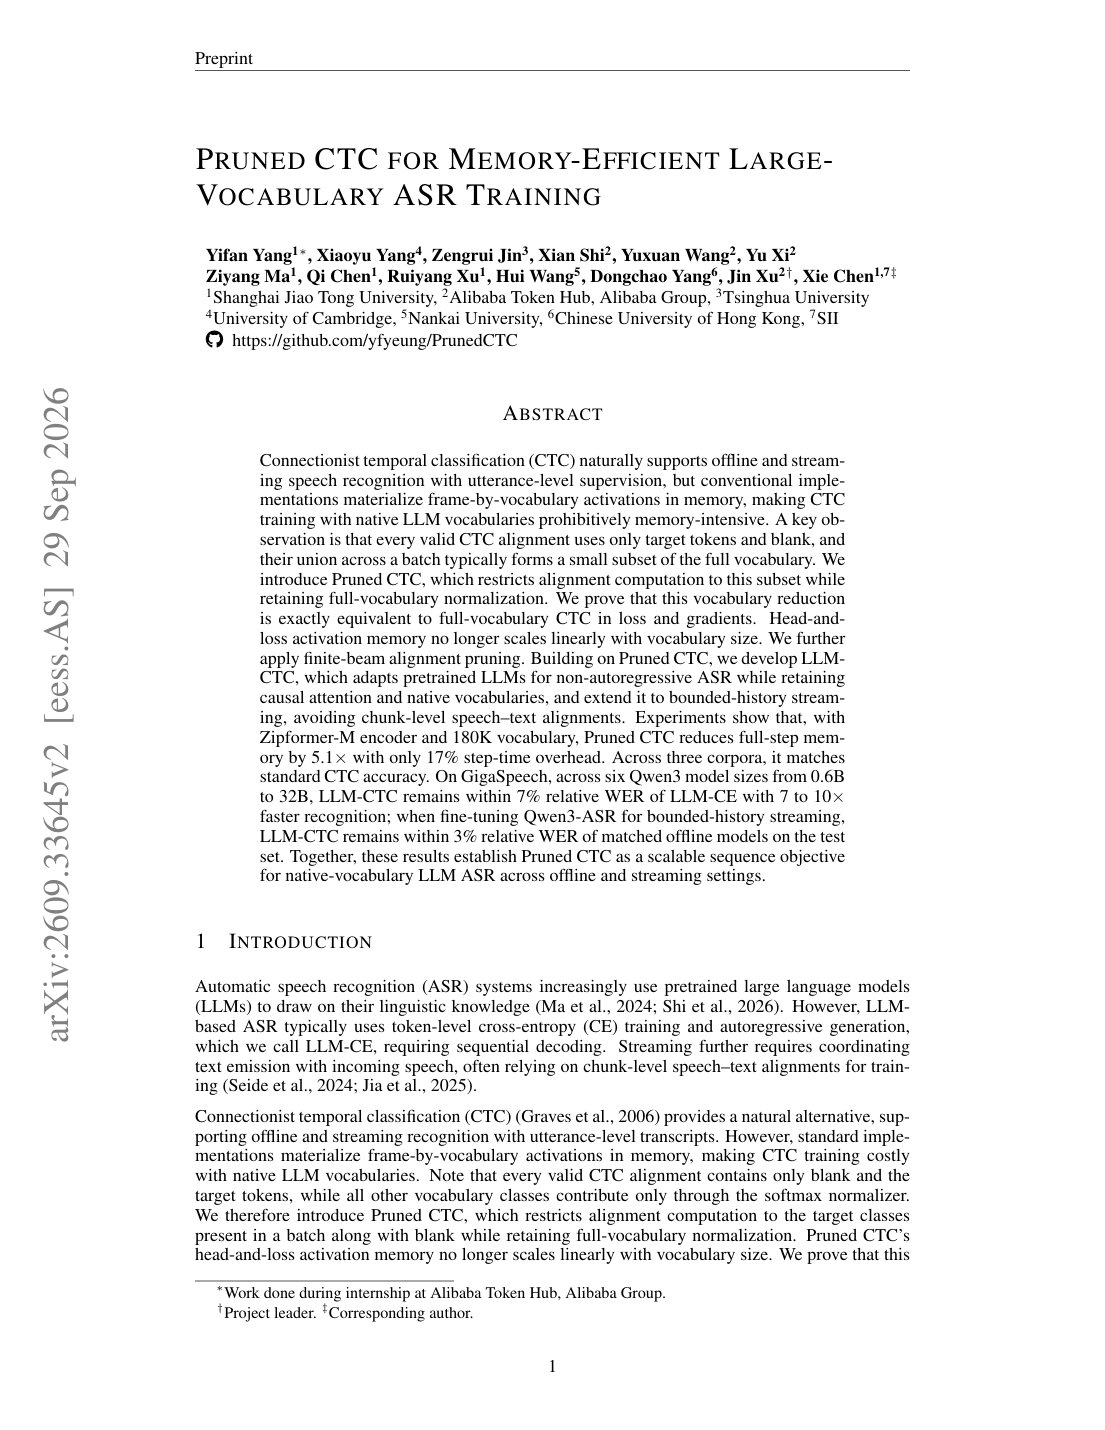
Pruned CTC Cuts 180K-Vocabulary ASR Training Memory
Restricting CTC alignment states to batch target tokens preserves full-vocabulary loss and gradients while cutting full-step memory 5.1× at 180K tokens.
Oct 4, 20264 min2609.33645
5 articles on SOTA Papers
Restricting CTC alignment states to batch target tokens preserves full-vocabulary loss and gradients while cutting full-step memory 5.1× at 180K tokens.
A streaming speech stack separates response text, function calls, transcription, and synthesis, reaching 82.5% tool-selection F1 while maintaining interruption handling.
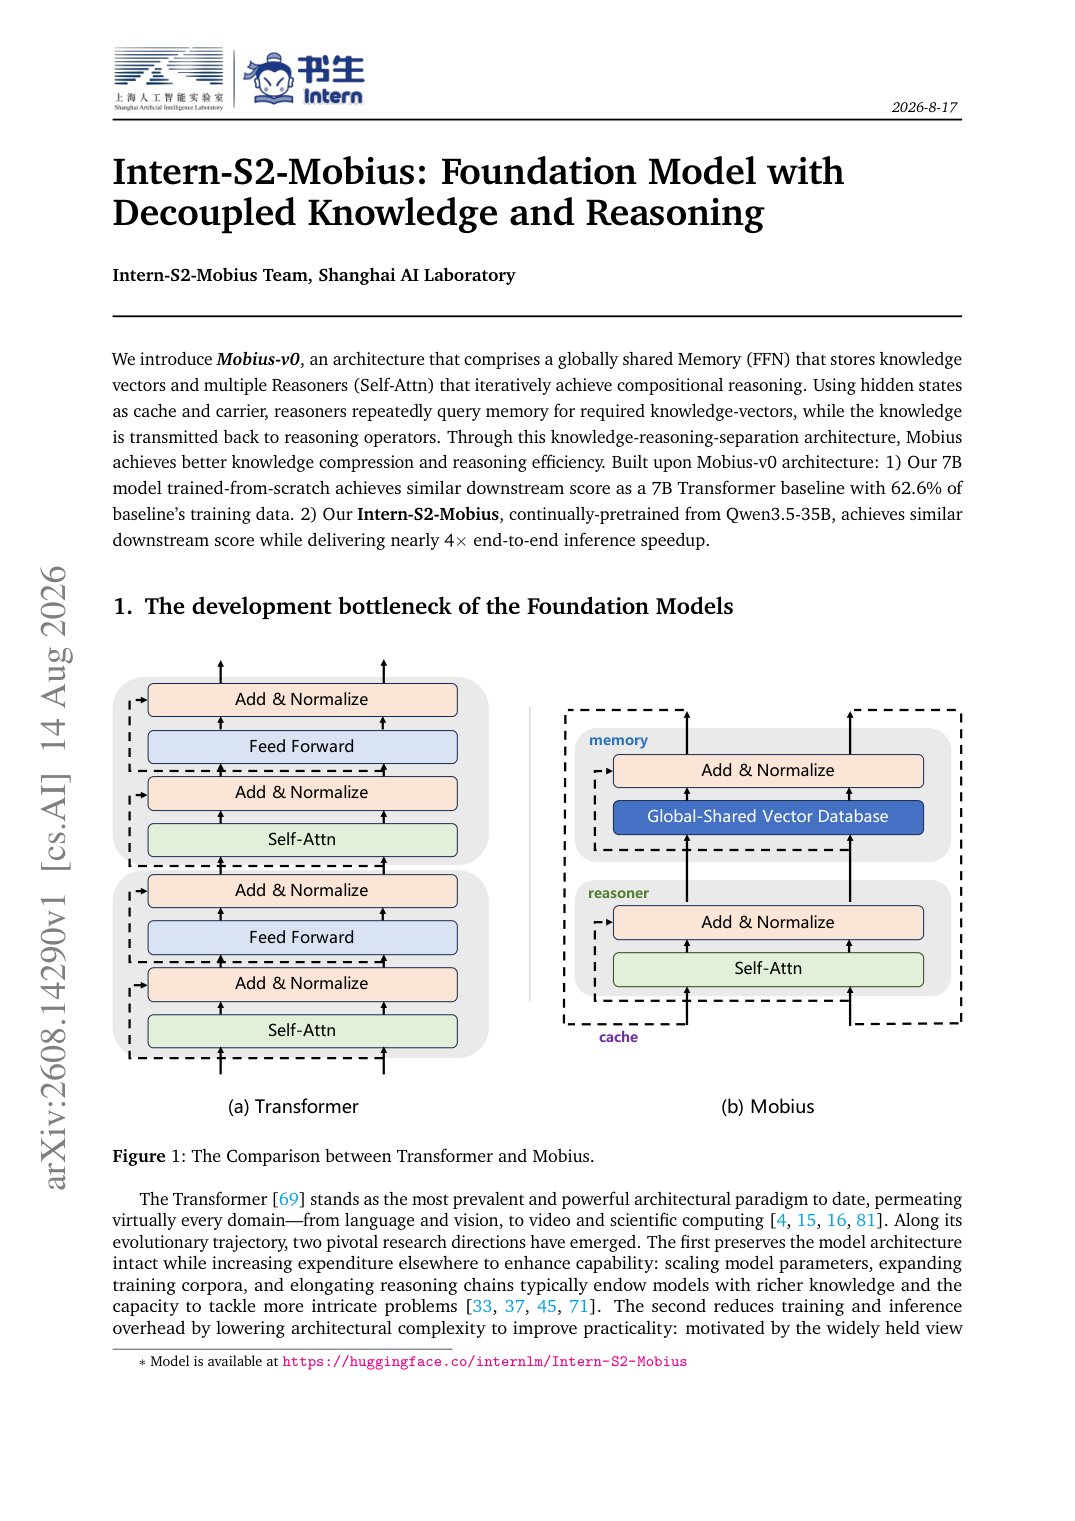
A shared feed-forward memory and iterative attention reasoners retain comparable downstream scores while reducing continual-pretrained 35B-model inference time by nearly 4×.
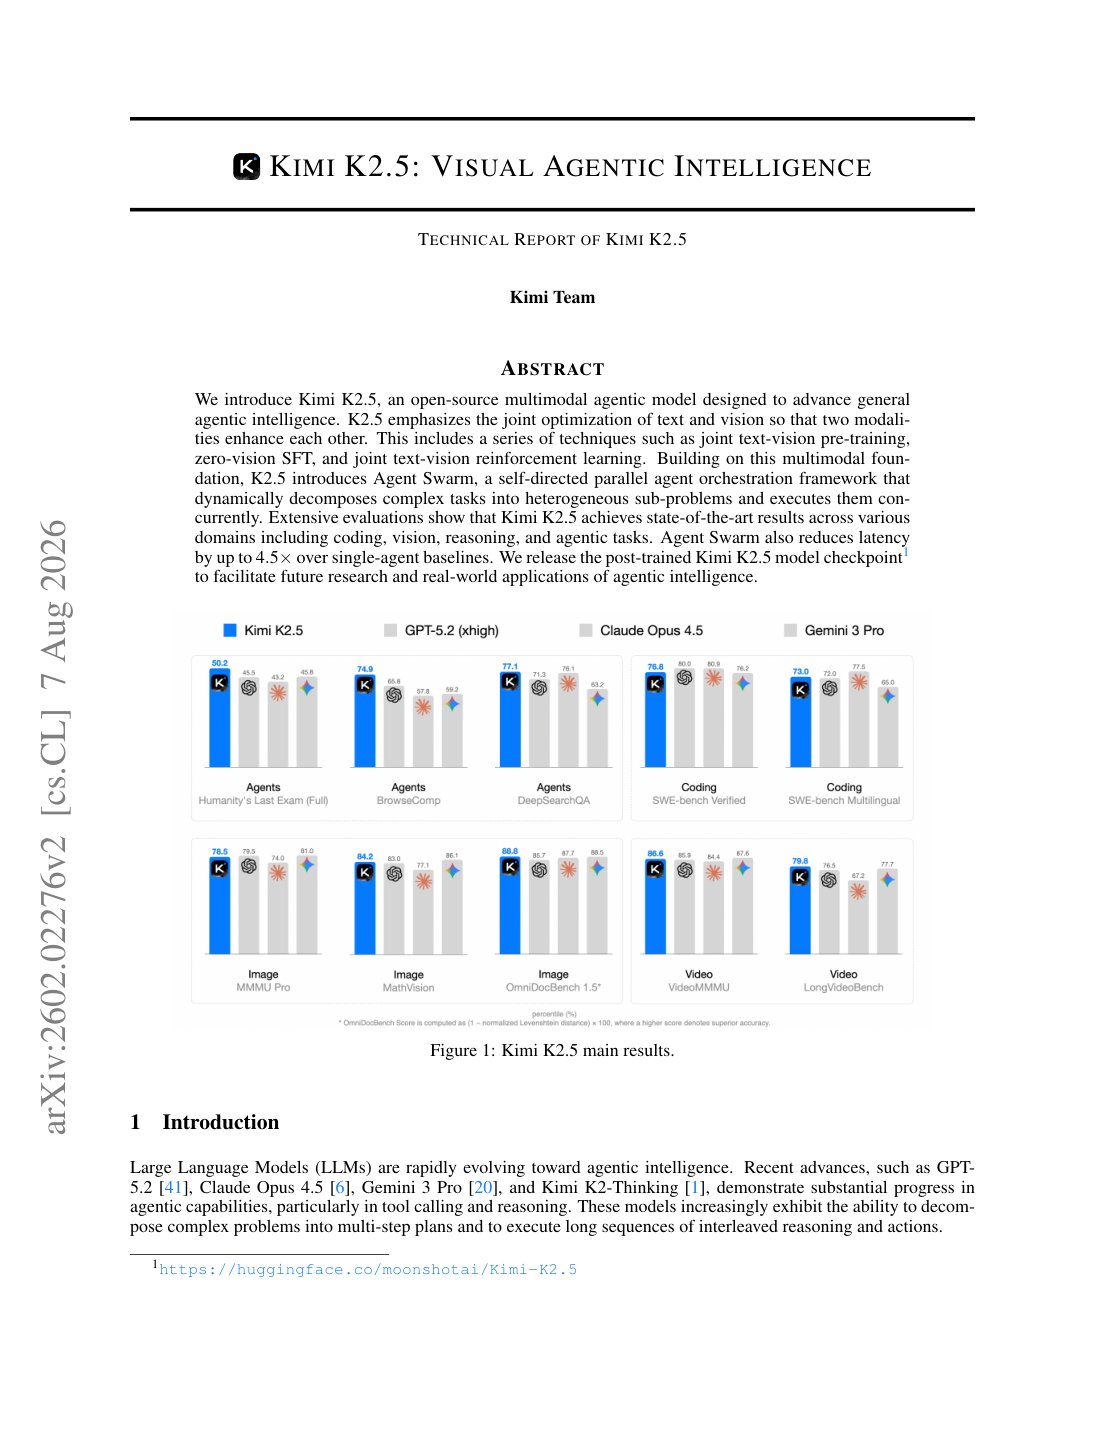
Kimi K2.5 couples joint text-vision training with dynamically scheduled parallel subagents, improving agentic search scores while reducing time to target quality.
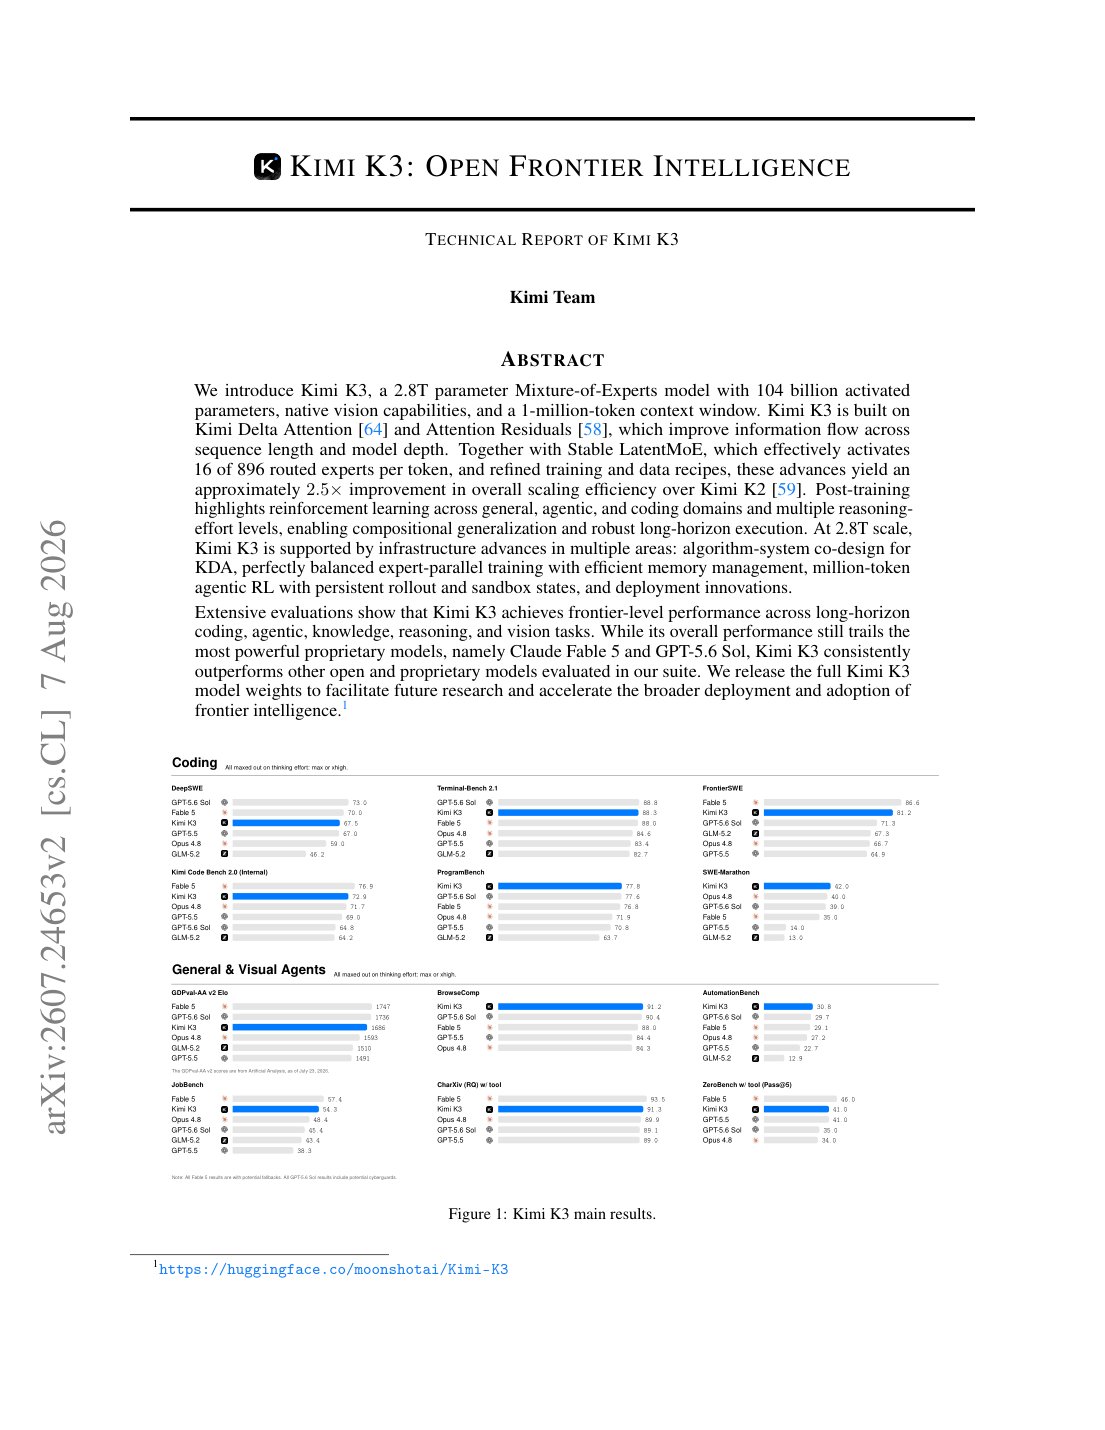
A 2.8T-parameter MoE combines Delta Attention, 16-of-896 expert routing, and agentic reinforcement learning to approach leading proprietary systems at lower task cost.