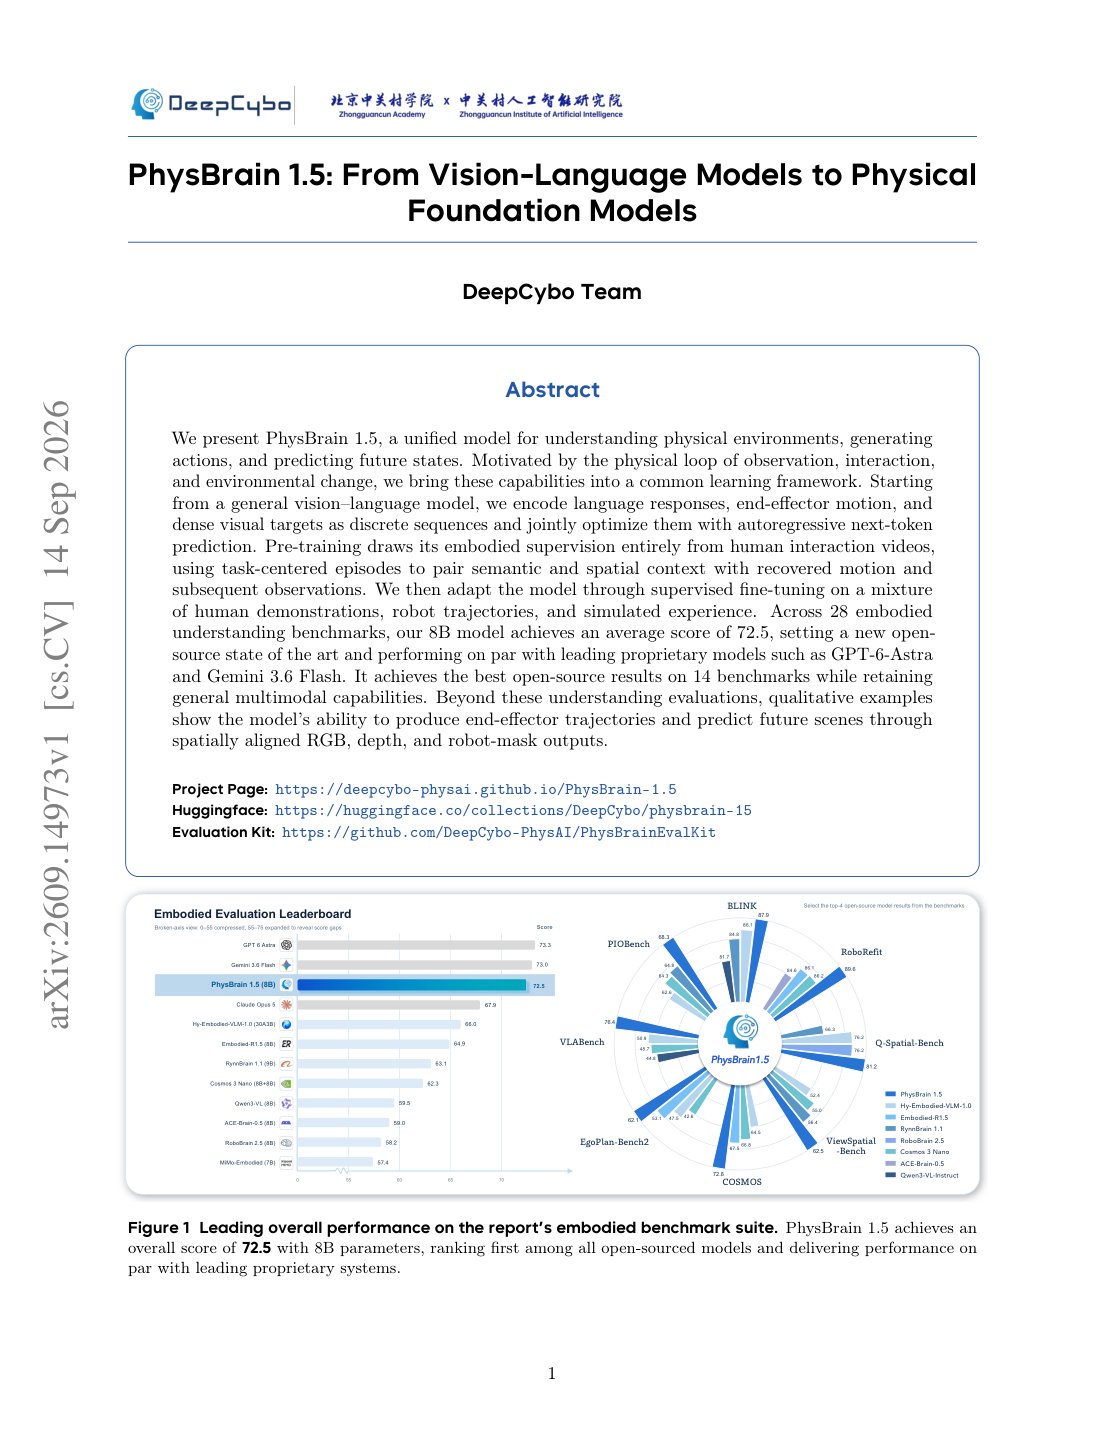
PhysBrain 1.5 Unifies Perception, Action, and Prediction
An 8B autoregressive model turns language, end-effector motion, and visual targets into one token stream, reaching a 72.5 average across 28 embodied benchmarks.
Sep 27, 20264 min2609.14973
2 articles on SOTA Papers
An 8B autoregressive model turns language, end-effector motion, and visual targets into one token stream, reaching a 72.5 average across 28 embodied benchmarks.
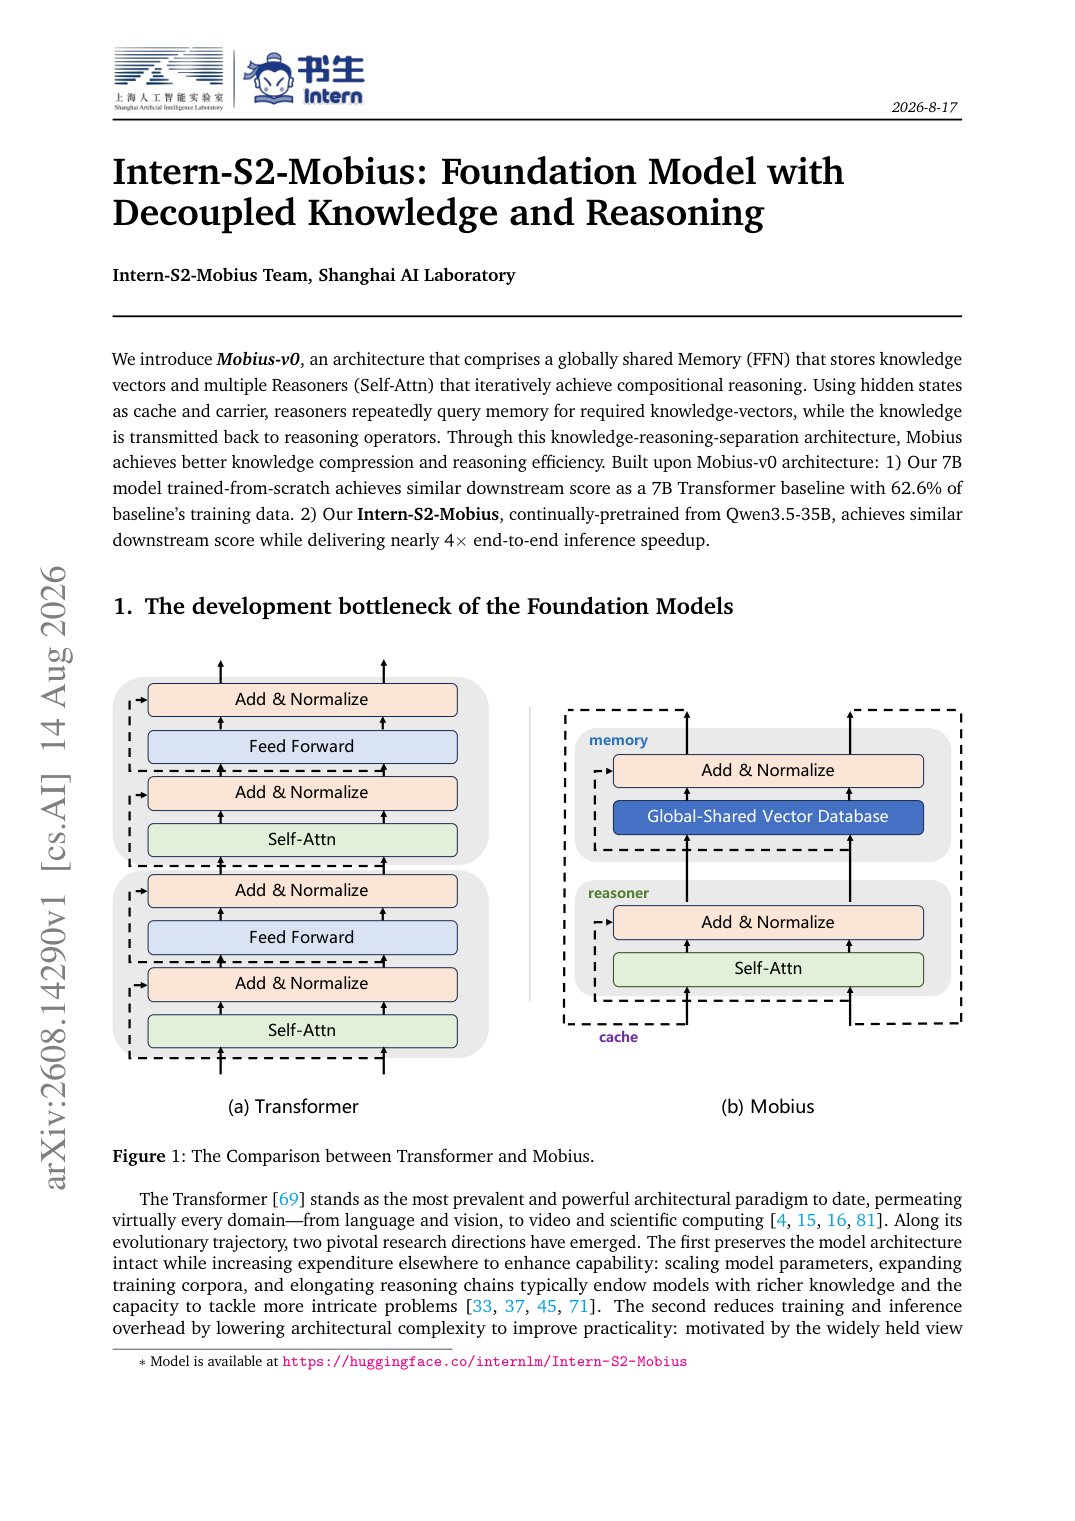
A shared feed-forward memory and iterative attention reasoners retain comparable downstream scores while reducing continual-pretrained 35B-model inference time by nearly 4×.