Streaming ASR Unifies Transcription and Speaker Attribution
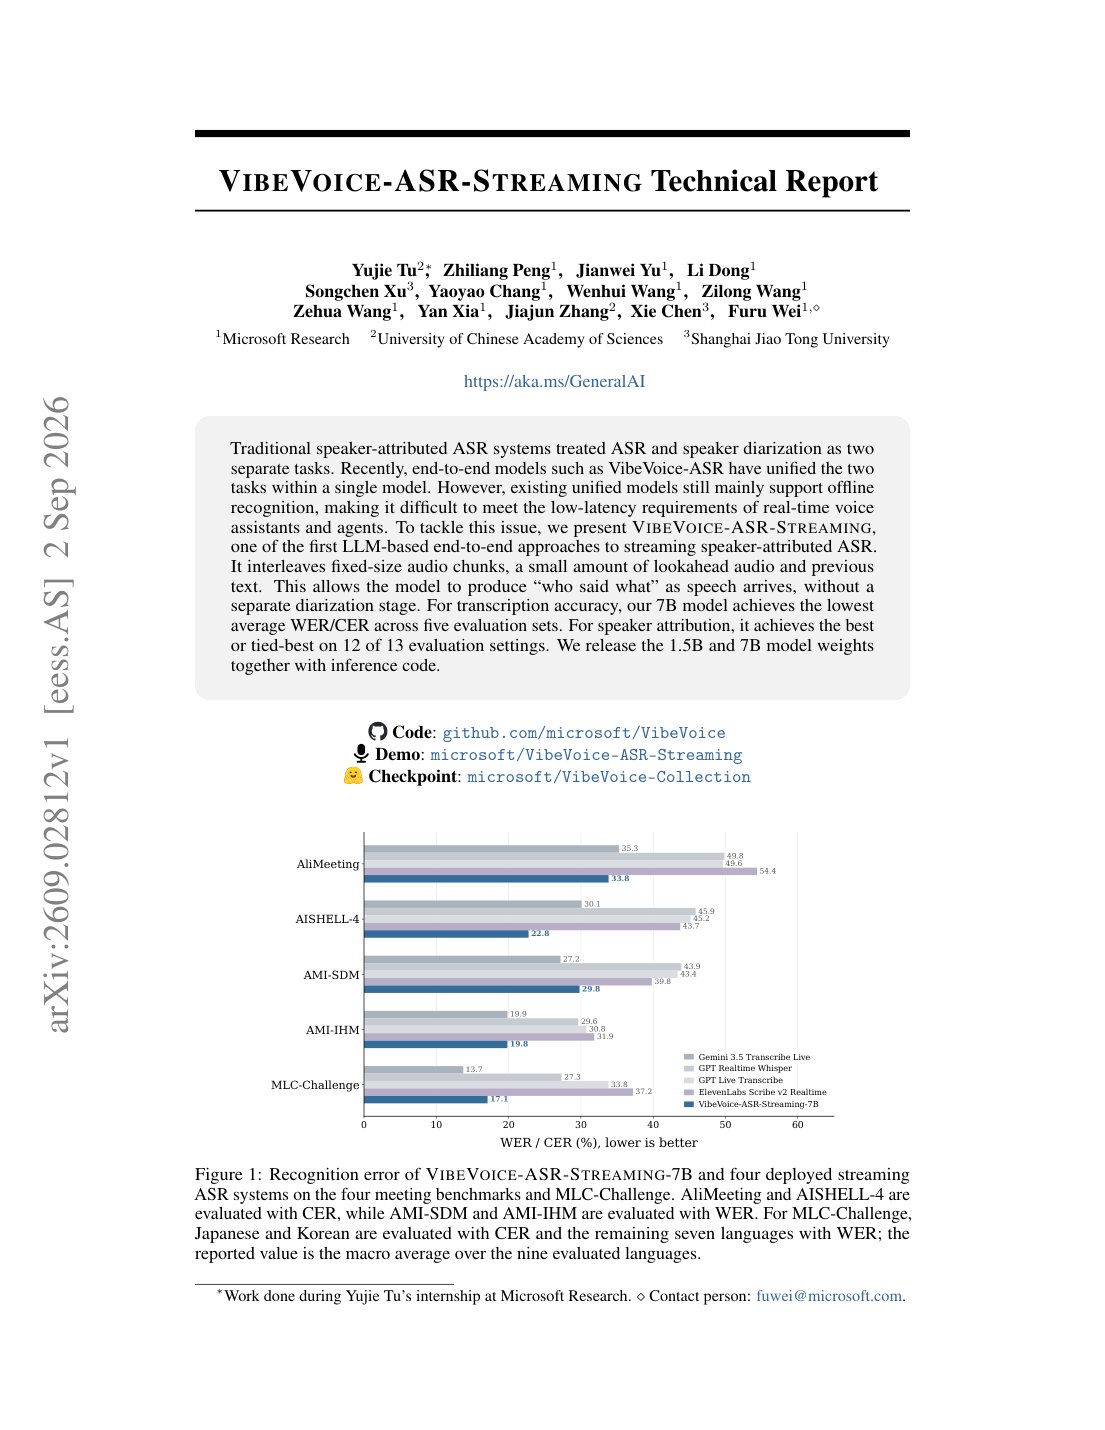
VibeVoice-ASR-Streaming interleaves audio, lookahead, and prior text so one model can produce speaker-attributed transcripts as speech arrives.
Sep 4, 20263 min2609.02812
3 articles on SOTA Papers
VibeVoice-ASR-Streaming interleaves audio, lookahead, and prior text so one model can produce speaker-attributed transcripts as speech arrives.
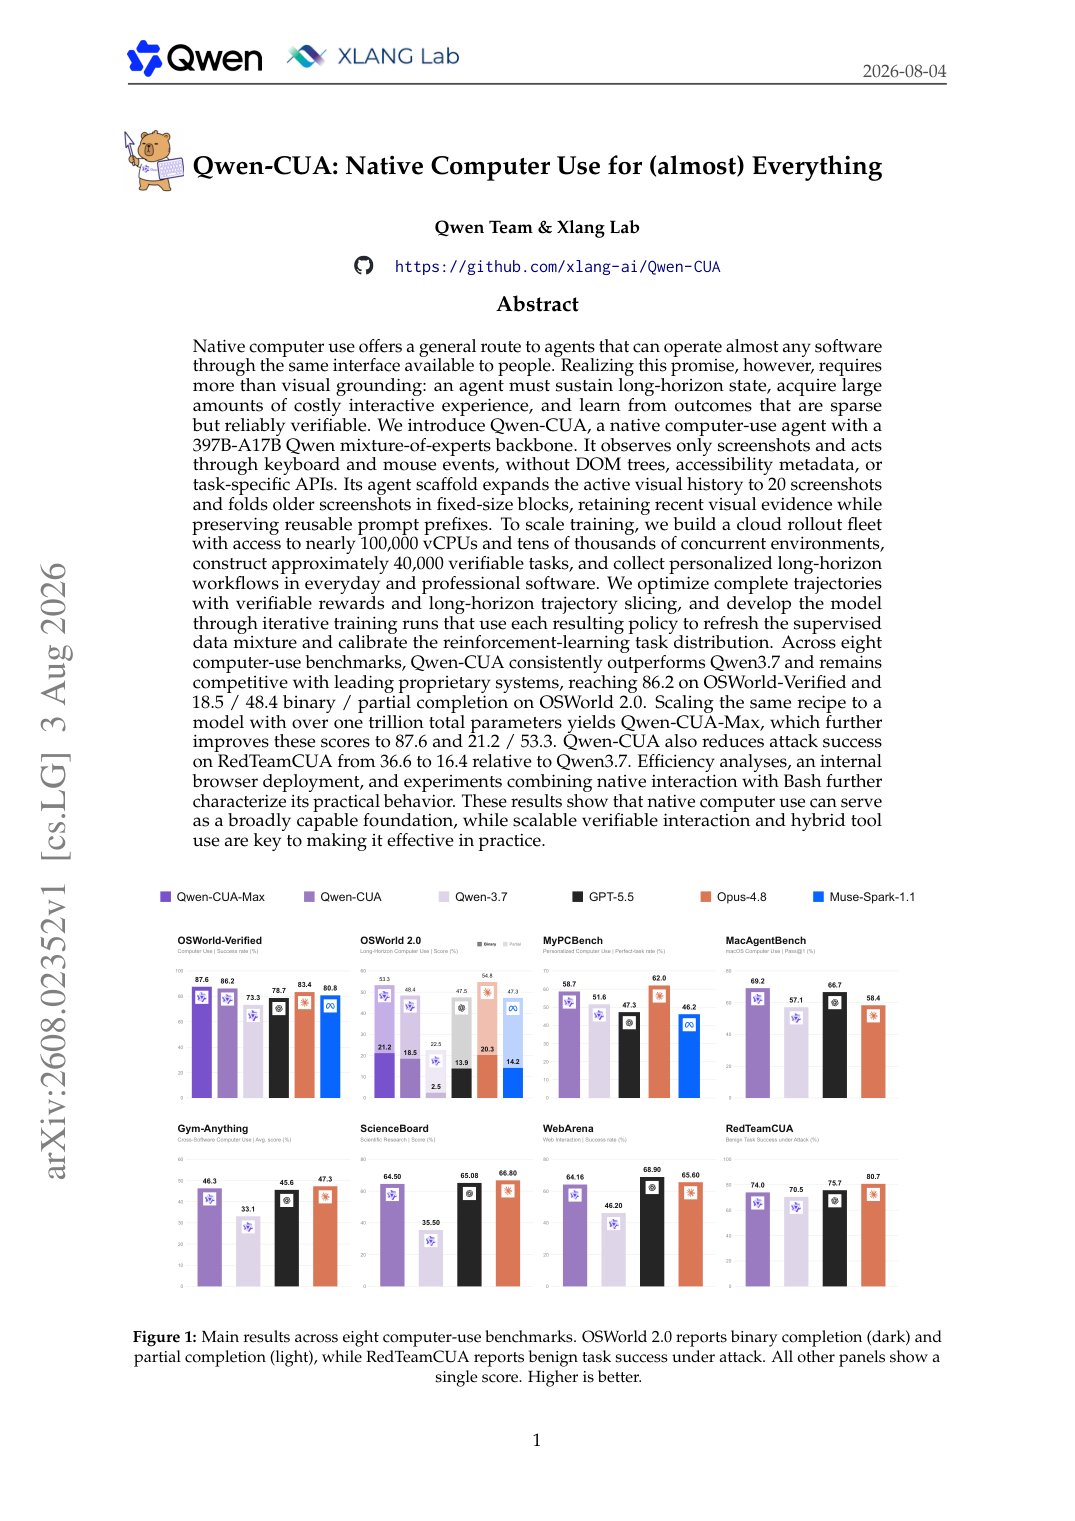
A 397B-A17B mixture-of-experts agent learns screenshot-only keyboard and mouse control from verifiable interactive trajectories, improving OSWorld-Verified performance to 86.2.
A 680-hour human-annotated benchmark combines multilingual, dialect, accent, domain, and age stress tests across ASR and speech translation.